
What if your GPU bill was optional? Amazon’s bet: TorchNeuron, an open-source PyTorch backend for its Trainium chips, entered public beta October 20, 2026 — running your existing PyTorch code on Trainium with one config change, no rewrite.
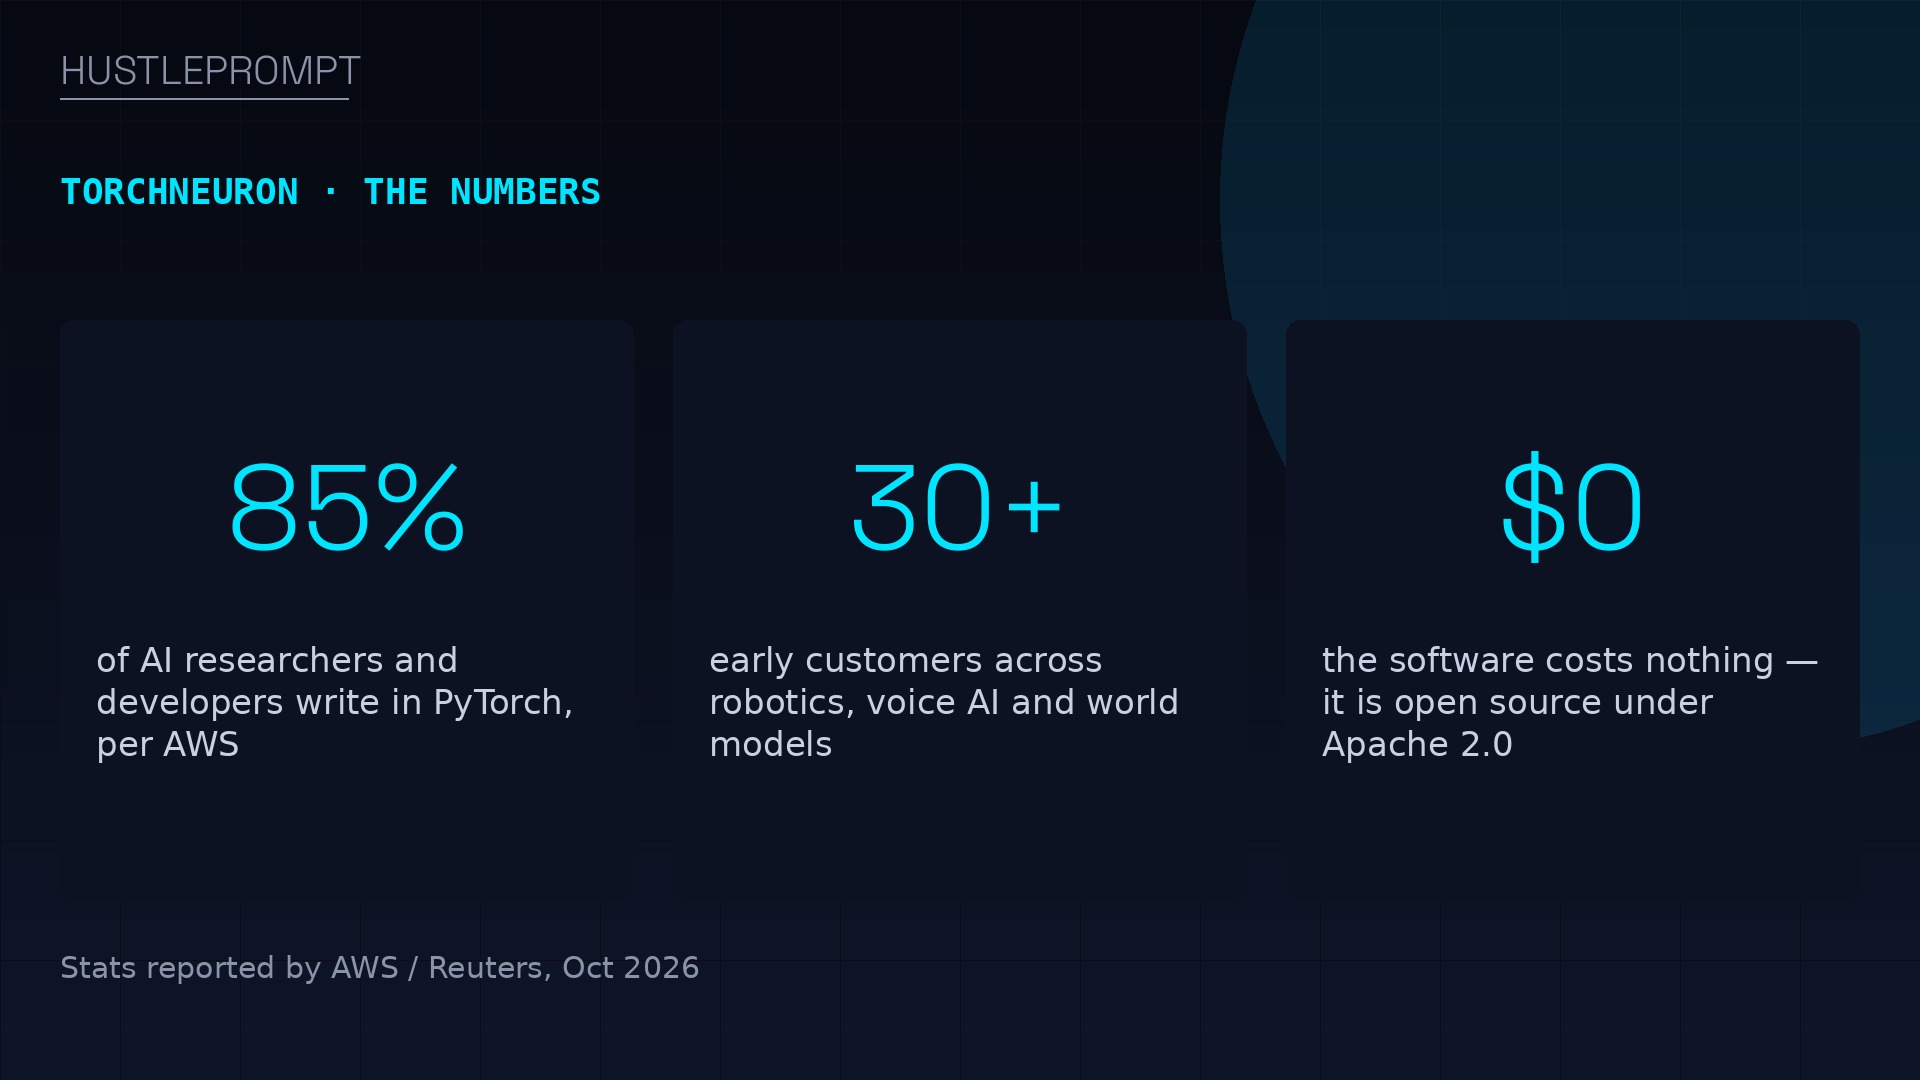
Amazon says about 85% of AI researchers and developers write in PyTorch — yet most still train on Nvidia, not because of the chips, but the CUDA software moat around them. TorchNeuron is a direct shot at that moat. Here is what shipped, what it costs (nothing — Apache 2.0), and how to turn it into money.
What TorchNeuron Actually Is
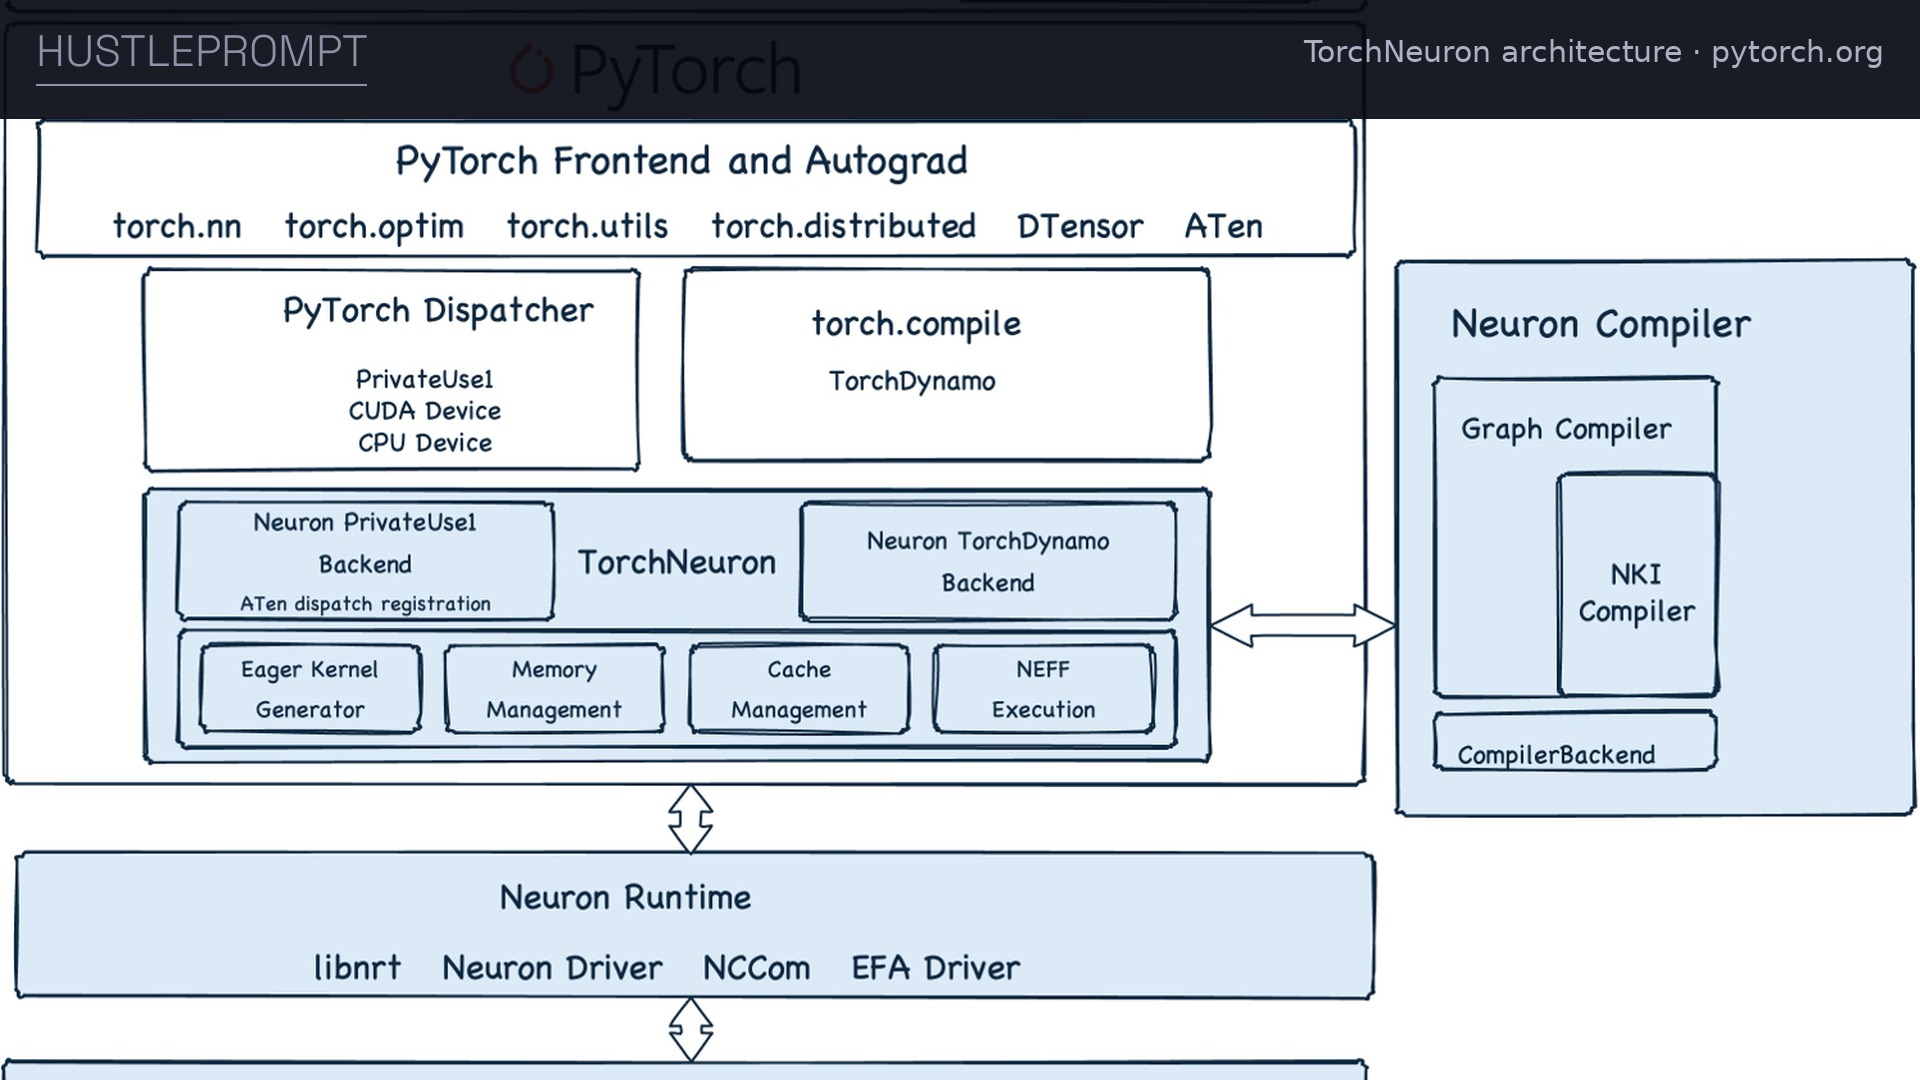
TorchNeuron registers AWS Trainium as a native PyTorch device through PrivateUse1, PyTorch’s official extension point for custom hardware. The APIs you already use — torch.nn, torch.autocast, torch.distributed, torch.profiler — work on Trainium.
The migration pitch is one line:
model = MyModel().to('neuron') # the only changeCode written against torch.accelerator runs unmodified. Compiled models just name the backend once — torch.compile(model, backend="neuron") — and TorchDynamo lowers the graph through Torch-MLIR into the Neuron compiler.
What ships in the box
- Eager mode for research and debugging, plus an experimental adaptive eager mode that approaches compiled-graph performance without a code change.
- torch.compile for production, with FlexAttention supported natively.
- Neuron Kernel Interface (NKI) for custom kernels, plus the open-source NKI-lib.
- Neuron Explorer profiling through the same
torch.profileryou already know. - Distributed training: DDP, FSDP2, tensor and pipeline parallelism.
For serving, vLLM Neuron is a vLLM plugin for LLMs, and vLLM Omni Neuron serves diffusion models. Hugging Face added native Trainium support — no AWS-specific code needed.
The Numbers That Matter
| Fact | Detail |
|---|---|
| Announced | October 19, 2026 (Amazon) |
| Public beta | October 20, 2026, at PyTorch Conference North America |
| License | Apache 2.0, at github.com/aws-neuron/torch-neuronx |
| Hardware | AWS Trainium2 and Trainium3 |
| Install | pip install torch-neuronx from the AWS Neuron pip repository |
| PyTorch share | ~85% of AI researchers and developers write in PyTorch, per AWS |
Source: PyTorch Foundation — “Introducing TorchNeuron: Native PyTorch backend for AWS Trainium”
Early Adopters: Who Is Already Saving Money
Amazon says more than 30 early customers — robotics, world models, voice AI, speech, drug discovery, finance — were already using TorchNeuron before the public beta, reporting steep cost savings.
| Early user | What they reported |
|---|---|
| Deepgram (voice AI) | ~60% more input audio seconds per dollar than its existing GPU baselines |
| Cartesia (voice AI) | Ran its standard inference pipeline on Trainium “with minimal changes” |
| Lieber Institute | Running drug-discovery and molecular-dynamics models on Trainium |
| Hugging Face, Anyscale, Decart, Modular, Nota AI | Native Trainium tooling support; named launch partners |
Sources: PyTorch Foundation announcement; Reuters reporting, October 19, 2026
How It Works: From Your Code to the Chip
TORCHNEURON EXECUTION FLOW
1 · Your code
Standard PyTorch model. One change: .to('neuron')
2 · TorchNeuron backend
Registers Trainium via PrivateUse1. Eager mode or torch.compile graph capture.
3 · Neuron compiler
TorchDynamo lowers the graph through Torch-MLIR into a NEFF file.
4 · Trainium chip
NEFF executes on Trainium2/Trainium3 over EFA.
Profiling via the same torch.profiler, visualized in Neuron Explorer.
Why This Is Really About Nvidia’s CUDA Moat
For a decade, Nvidia’s grip on AI training was not just silicon — it was software integration. CUDA made PyTorch code fast on Nvidia GPUs by default. AWS is attacking exactly that layer: if switching chips costs one config line, the hardware decision becomes about price-performance. Amazon also contributed code upstream to remove hard-coded CUDA assumptions; shares climbed as much as 5% intraday on the news.
The honest caveat: “no rewrite” is not “no work.” In AWS’s August 2026 upstream test run, about 39,000 of ~154,000 outcomes were deliberate Neuron skips — ~22,000 operators lack native lowering yet. Sparse tensors, forward-mode autograd and dynamic shapes are not in the first release, and FP8 is in private beta. Benchmark your own workload first.
How to Profit From TorchNeuron
Every workload renting Nvidia GPUs is a candidate for a cheaper Trainium run. Here is the playbook:
1. Sell compute audits with a benchmark
Offer startups a fixed-fee GPU spend audit: profile their jobs, then run the same job on Trainium with the one-line switch. The Deepgram precedent — 60% more audio per dollar — is your sales reference.
2. Package Trainium migrations
Sell a repeatable service: port a training loop or vLLM serving stack to Trainium, validate outputs match, hand over runbooks. Your margin is in validation, not the rewrite.
3. Ship Trainium-first templates
Build ready-to-deploy templates — fine-tuning, RAG serving with the vLLM Neuron plugin — and sell them as one-time products to AI agencies.
4. Cut your own compute bill
If you train or serve models yourself, every dollar saved is margin. Test your heaviest job on Trainium while the beta is frictionless.
Frequently Asked Questions
Is TorchNeuron really free?
Yes — Apache 2.0 at github.com/aws-neuron/torch-neuronx, free for commercial use. You still pay for Trainium compute.
Which chips does it support?
Trainium2 and Trainium3 at launch, for training and inference.
Do I have to rewrite my PyTorch code?
No. Point your model at the neuron device; torch.accelerator code runs unmodified. Compiled models name the backend once.
How do I install it?
pip install torch-neuronx from the AWS Neuron pip repository, starting with the October 20, 2026 public beta.
Is performance identical to Nvidia GPUs?
Not guaranteed. AWS showed comparable learning rates in a demo, but ~22,000 operators lacked native lowering in August testing. Benchmark your own workload.
Does it work with Hugging Face?
Yes. Hugging Face added native Trainium support to its tools, so Transformers and Diffusers users need no AWS-specific code.
Sources
- PyTorch Foundation — Introducing TorchNeuron: Native PyTorch backend for AWS Trainium
- TorchNeuron on GitHub (aws-neuron/torch-neuronx)
- AWS Trainium official page
- AWS Neuron SDK official page
KEEP READING