
It beats Claude Opus 5 on coding benchmarks and costs $0.15 per million input tokens. The new DeepSeek V4.1 Flash snapshot — labeled 1017, released October 17, 2026 — is the cheapest agent-grade AI in the world right now, with MIT-licensed weights on Hugging Face and a 1-million-token context window.
DeepSeek pushed the update across its website, app, and API in one move, and called it a Pareto improvement: better scores, faster task completion, and shorter outputs than the model it replaces. The API name didn’t change — deepseek-flash just got a lot better overnight.
What the 1017 snapshot actually is
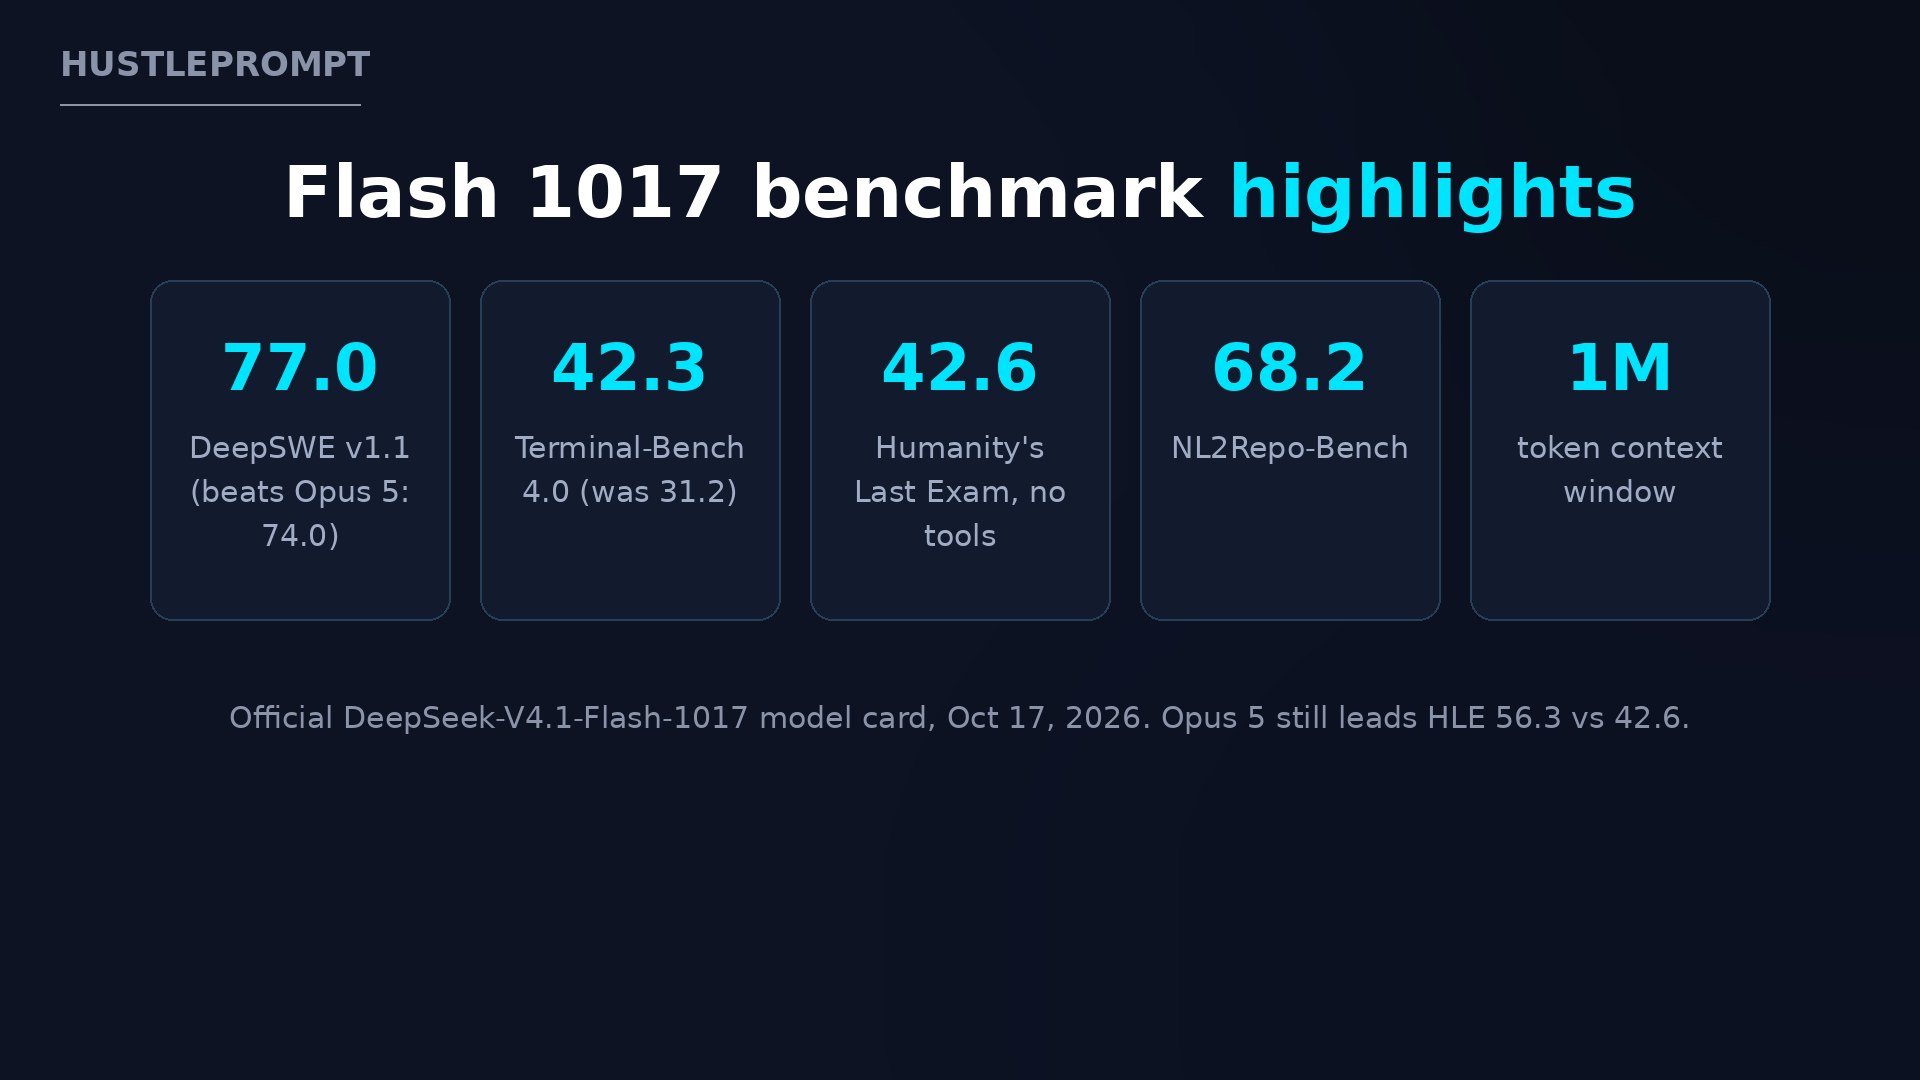
DeepSeek describes 1017 as a minor update to V4.1 Flash with substantial improvements across reasoning, coding, agentic tasks, and visual benchmarks — plus reduced task execution time and output length, which is where the real cost savings hide.
| Benchmark | Flash 1017 | Prev. Flash | Claude Opus 5 |
|---|---|---|---|
| DeepSWE v1.1 | 77.0 | 74.2 | 74.0 |
| Terminal-Bench 4.0 | 42.3 | 31.2 | 51.8 |
| HLE (no tools) | 42.6 | 36.8 | 56.3 |
| ProgramBench | 29.1 | 20.3 | 37.0 |
| NL2Repo-Bench | 68.2 | 65.4 | 75.3 |
Data: official DeepSeek-V4.1-Flash-1017 model card, October 17, 2026. Be honest about the full picture: 1017 beats Opus 5 on DeepSWE (77.0 vs 74.0) but still trails it on HLE (42.6 vs 56.3) and Terminal-Bench.
The pricing that changes the math
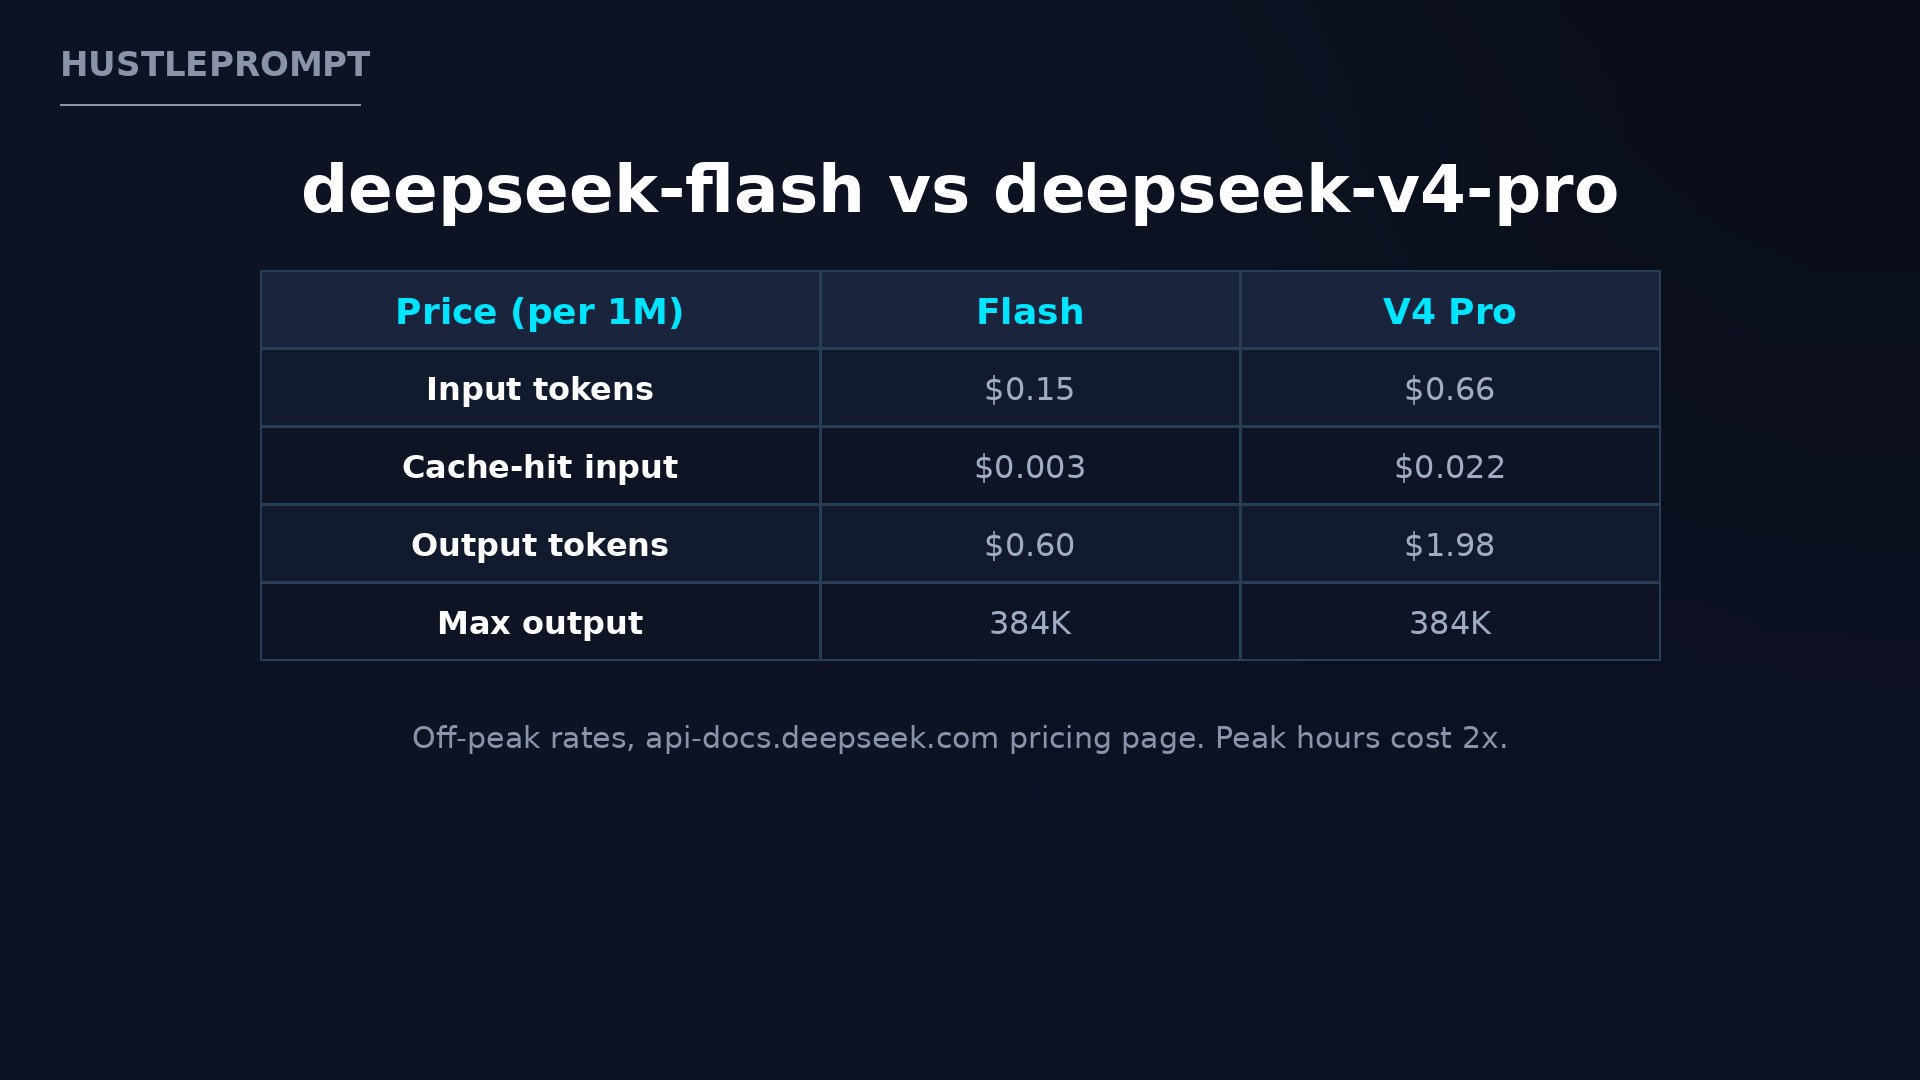
DeepSeek’s own rate card tells the story. Off-peak pricing for deepseek-flash — now served by the 1017 snapshot — against the bigger deepseek-v4-pro:
| Price (per 1M tokens) | deepseek-flash | deepseek-v4-pro |
|---|---|---|
| Input (cache miss) | $0.15 | $0.66 |
| Input (cache hit) | $0.003 | $0.022 |
| Output | $0.60 | $1.98 |
| Max output | 384K tokens | 384K tokens |
Off-peak rates from api-docs.deepseek.com pricing. Peak hours cost double — weekdays 01:00–04:00 and 06:00–10:00 UTC, excluding Chinese public holidays.
How it works
Getting onto 1017 takes minutes. Three steps:
- Point your code at
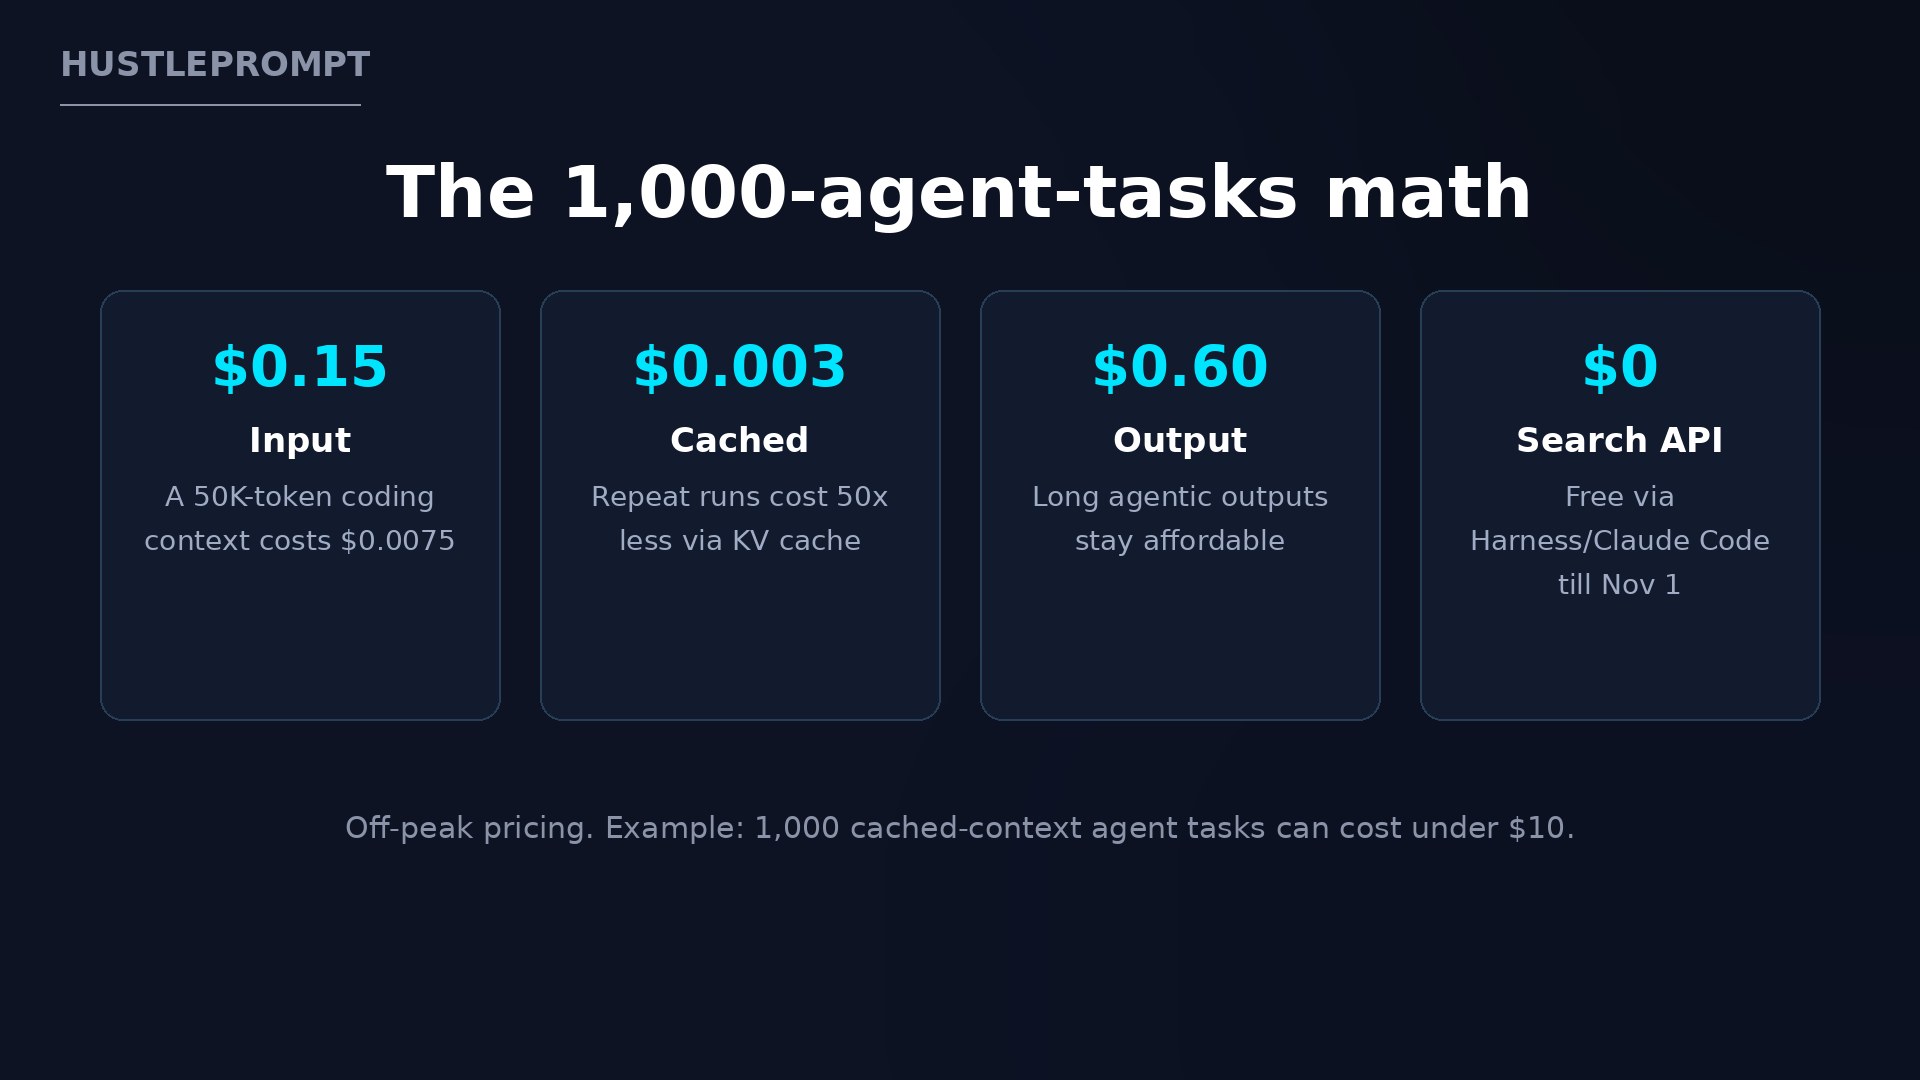
deepseek-flash. The API is OpenAI- and Anthropic-compatible, so swapping the model name is usually a one-line change. The legacy namesdeepseek-v4-flashanddeepseek-v4-flash-vision-expstill work — their requests are now served by 1017 and billed at the Flash price. - Turn on context caching. Agent work repeats the same big context every turn. Cache-hit input costs $0.003 per million tokens versus $0.15 for a cache miss — a 50x difference that compounds across thousands of agent loops.
- Plug it into your agent tools. DeepSeek Harness, Claude Code, GitHub Copilot, and OpenCode all accept DeepSeek as a backend model with no code required, per the official integration docs.
How to profit with DeepSeek V4.1 Flash
When the marginal cost of an agent task rounds to fractions of a cent, business models that were impossible become boring. Four plays:
- Run coding-agent services at near-zero marginal cost. A 50K-token coding context costs $0.0075 off-peak. Bug-fix bots, code-review pipelines, and repo-migration services can price per deliverable while the API cost stays invisible.
- Build on the MIT weights. The 1017 weights are MIT-licensed on Hugging Face and ModelScope. Self-host for fixed costs, fine-tune for a niche, or sell a specialized version — no licensing friction.
- Ship products the Search & Fetch APIs unlock. DeepSeek just opened its in-house search engine: $0.75 per 1,000 successful requests. Server-side calls through DeepSeek Harness, Claude Code, or Codex are free until November 1, 2026 at 00:00 Beijing time — a window to prototype search-powered agents at zero cost.
- Sell the arbitrage honestly. Wrap Flash in a managed product — “unlimited” code review, SEO content pipelines, support-ticket triage — and price on value, not tokens. The spread between a $29/month seat and pennies of API cost is the business.
Cost of 1M input + 1M output tokens (off-peak)
$0.75
$2.64
Flash costs about 3.5x less for the same token volume — computed from DeepSeek’s official off-peak rate card. Bar widths are proportional ($0.75 vs $2.64).
The honest caveats
Don’t buy the hype wholesale. Opus 5 still leads Flash 1017 on Humanity’s Last Exam (56.3 vs 42.6) and Terminal-Bench 4.0 (51.8 vs 42.3) — the “on par with Opus 5” chatter is mood, not the model card. Peak-hour pricing also doubles the rate card, so schedule heavy batch jobs off-peak.
FAQ
What is DeepSeek-V4.1-Flash-1017?
The October 17, 2026 snapshot of DeepSeek V4.1 Flash. DeepSeek calls it a minor update with substantial gains in reasoning, coding, agentic tasks, and visual benchmarks — plus faster task completion and shorter outputs.
Do I need to change my API code?
No. Keep calling deepseek-flash — it is now served by the 1017 checkpoint automatically, and pricing is unchanged. The old deepseek-v4-flash and deepseek-v4-flash-vision-exp names still work and are billed at the Flash price.
How much does DeepSeek V4.1 Flash cost?
Off-peak: $0.15 per million input tokens, $0.003 per million cache-hit tokens, $0.60 per million output tokens. Peak hours (weekday mornings UTC) cost double.
Can I run the model myself?
Yes. The weights are on Hugging Face and ModelScope under the MIT license. DeepSeek recommends temperature 1.0 and top_p 1.0, with a 1M-token context window.
When does the free Search API window end?
Server-side Search and Fetch calls through DeepSeek Harness, Claude Code, or Codex are free until 00:00 Beijing time on November 1, 2026. After that, per-request billing ($0.75 per 1,000 successful requests) applies.
Is it really better than Claude Opus 5?
On DeepSWE v1.1, yes: 77.0 vs 74.0. But Opus 5 still leads on Humanity’s Last Exam and Terminal-Bench. Flash 1017 is the better value play, not an across-the-board winner.
Keep Reading
- DeepSeek V4.1 Flash: Dirt-Cheap AI for High-Volume Work
The original V4.1 Flash launch — what 1017 improves on. - DeepSeek Down 5 Hours: The Hidden Cost of Cheap AI
Cheap is great until it’s down — plan for outages. - Microsoft’s 2.8T MAI-Base-2 Beats OpenAI on 1/4 Compute
The efficiency race Flash 1017 is part of.