
A new AI model just rewrote the speed rules. Mercury 3, launched by Inception on October 19, 2026, generates text at a staggering 1,068 tokens per second — with benchmark scores matching GPT-6 Luna and Claude Haiku 5.5, at half the launch price.
For agent builders and AI service sellers, this matters now. Latency is the silent killer of agent businesses: every extra second multiplies across dozens of model calls per task — and Mercury 3’s OpenAI-compatible API means switching takes a one-line change.
Mercury 3 at a glance
Official numbers from Inception’s official announcement (Oct 19, 2026):
| Spec | Mercury 3 | Source |
|---|---|---|
| Speed | 1,068 tokens/second on NVIDIA GPUs | Company announcement |
| Context | 1M tokens (up from 260K on Mercury 2.5) | Official press release |
| Scale | 40x+ the size of Mercury 1, same speed class | Official press release |
| Benchmarks | On par or better than GPT-6 Luna and Claude Haiku 5.5, running 4–8x faster* | Company claim |
| Launch price | $0.10 input / $0.35 output per 1M tokens (50% off) | Official press release |
| Access | Inception API, Baseten, OpenRouter, Vercel | Official press release |
*Benchmark comparisons are Inception’s own figures. No independent evaluations exist yet — treat them as the company’s claim, not verified fact.
What is a diffusion LLM, and why is it so fast?
Nearly every major model — GPT-6, Claude, Gemini — is autoregressive: it writes one token at a time, left to right, like typing. An early error can poison the rest, and speed is capped by that sequential chain.
Mercury 3 is a diffusion LLM. Instead of typing word by word, it generates many tokens in parallel and refines the whole draft from coarse to fine — like an editor revising an entire page at once. That parallelism maps perfectly onto what GPUs do best: lots of math at once.
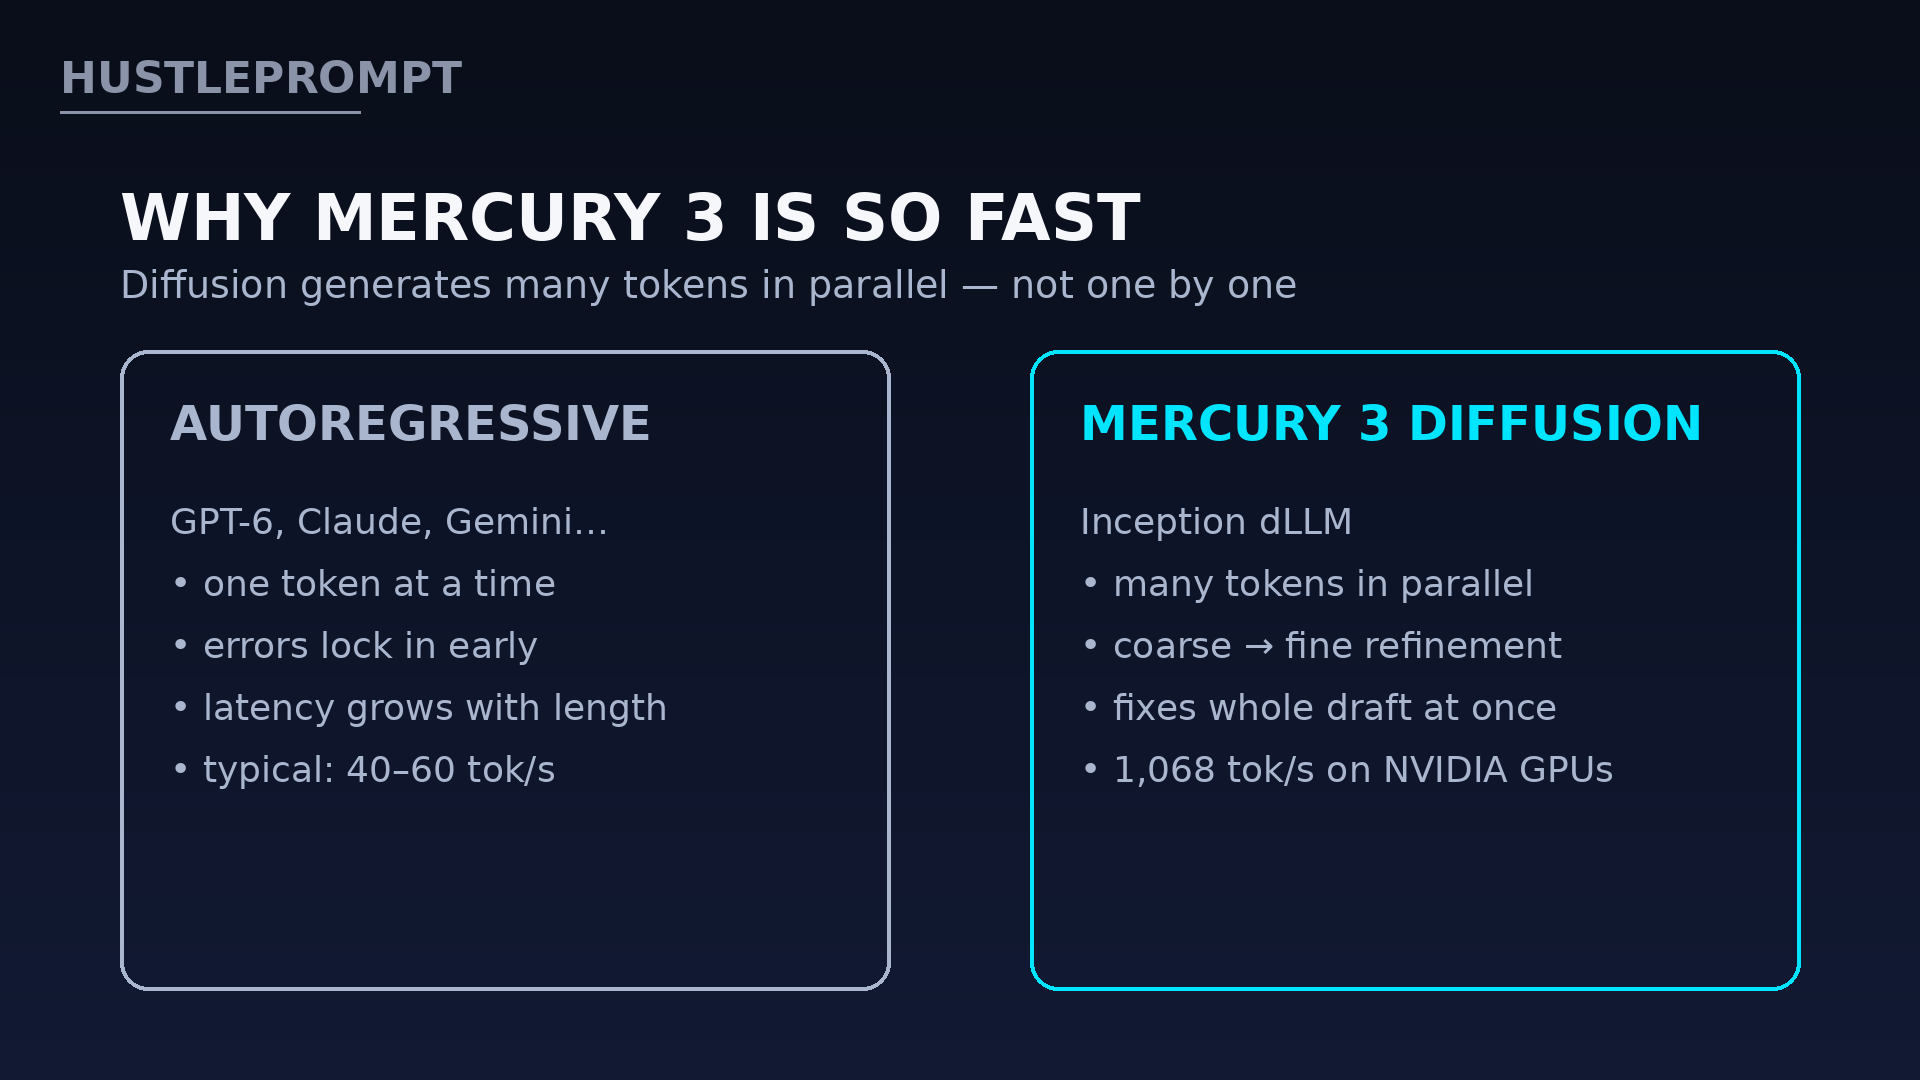
How Mercury 3 generates an answer
- Draft: sketch the entire answer at once, starting from noise.
- Refine: improve all parts of the draft simultaneously, several passes deep.
- Polish: lock in structure, facts and formatting in one final pass.
Result: 1,068 tokens/second — roughly 15–20x faster than typical frontier models at 40–60 tokens/second.
The evidence: early customer results
Inception shared production results from three early-access partners (company-reported, not independent):
- RevisionDojo: “hints, marked answers and definitions now come back in about a second, with quality as good as or better than the models we ran before,” said co-founder and CTO Michael Tong. A drop-in swap for their stack.
- TinyFish AI: completed half of 50 live Mind2Web browser-navigation tasks in production.
- Octen AI: median generation time of 0.9 seconds, median end-to-end response of 2.2 seconds.
CEO Stefano Ermon added that Inception ran swarms of Mercury 3 agents on recursive self-improvement — boosting the model’s own speed another 16%. His thesis: “The limits to scaling diffusion models are compute and data, not fundamental algorithmic barriers.”
Mercury 3 pricing: the cheapest fast intelligence right now
| Tokens | List price / 1M | Launch price / 1M |
|---|---|---|
| Input | $0.20 | $0.10 (50% off) |
| Output | $0.70 | $0.35 (50% off) |
| Cached input | $0.02 | $0.01 (90% off input) |
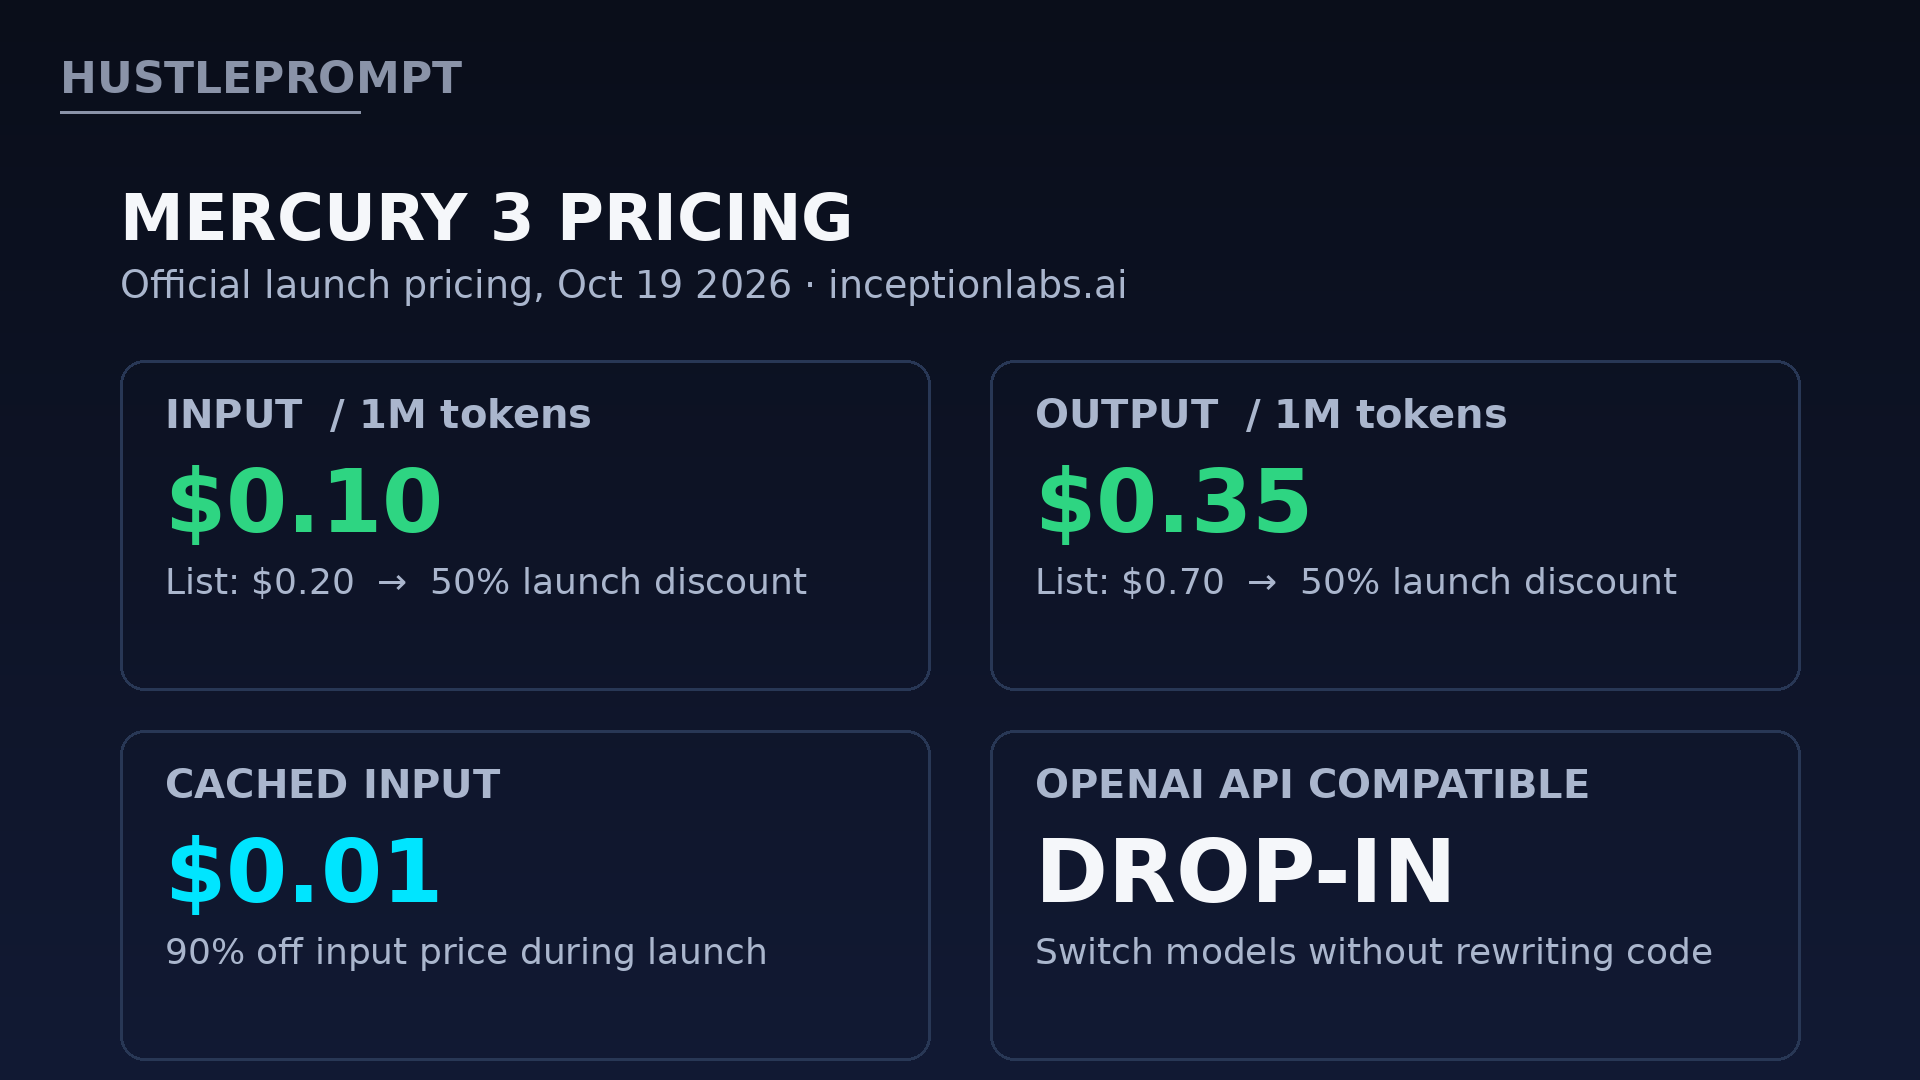
Inception hasn’t said when the 50%-off promotion ends — but Ermon told The Deep View the company is working toward making the launch price permanent. Mercury 2 and 2.5 are closed to new users; existing non-enterprise users must migrate by November 15, 2026.
How to profit from Mercury 3: 5 concrete plays
1. Drop-in swap your existing pipelines
Mercury 3 is OpenAI API compatible — switching usually means changing the base URL and model string. If you run agents on GPT-6 Luna or Claude Haiku 5.5, benchmark Mercury 3 on your own tasks while the launch price holds.
2. Build agents where latency was the blocker
Agent loops call the model dozens of times per task, and delays compound. A 4–8x faster model turns agents that took minutes into agents that take seconds — the difference between a demo and a product customers pay for.
3. Ship real-time products
Interactive tutoring, live assistants, real-time translation: these live or die on responsiveness. At roughly a second per answer, Mercury 3 makes “instant” a feature you can sell.
4. Sell migration help before November 15
Mercury 2/2.5 non-enterprise users lose access November 15, 2026. If you consult on AI infrastructure, offer migration audits and Mercury 3 rewiring now.
5. Lock in the launch discount for your margins
At $0.10/$0.35 per million tokens, a 10,000-token agent task costs roughly half a cent. Build and price your service on today’s rates.
FAQ
What is Mercury 3?
Inception’s newest diffusion-based language model, announced October 19, 2026. It generates text in parallel rather than one token at a time: 1,068 tokens per second with a 1-million-token context window.
Is Mercury 3 really better than GPT-6 Luna or Claude Haiku 5.5?
That’s Inception’s claim from its own benchmarks — no independent evaluation exists yet. Treat it as a strong signal to test on your own workloads, not proven fact.
How much does Mercury 3 cost?
List: $0.20 per million input tokens, $0.70 output. Launch: 50% off at $0.10 input and $0.35 output, with cached input at $0.01. Inception hasn’t announced when the promotion ends.
What is a diffusion LLM?
A language model that drafts many tokens in parallel and refines the whole answer from coarse to fine — the principle behind diffusion image models. Traditional models predict one token at a time.
How do I use Mercury 3 in my app?
Through the Inception API, Baseten, OpenRouter or Vercel. It’s OpenAI API compatible, so in most codebases you only change the base URL and model name.
Will the launch pricing last?
Unknown. No end date was announced, and CEO Stefano Ermon said Inception is working toward making the launch price permanent. Build on today’s rates, but don’t assume they’re forever.
Keep Reading
Sources: Inception’s official Mercury 3 press release (Business Wire, Oct 19, 2026); Inception Labs. Benchmark and speed figures are company-reported.