
Sixty percent off, zero code changes. Perplexity just flipped its Agent API presets to Fast Search — and perplexity fast search agent api pricing means every web_search call under those presets now costs $1.00 instead of $2.50 per 1,000 invocations, arriving about 800 milliseconds faster. If you run AI agents that search the web, your bill just shrank while you slept.
Straight from Perplexity’s official API changelog (October 2026): low, medium, high and xhigh presets now default to Fast Search for web_search. Models, prompts, budgets and step limits are unchanged — a pure price-and-speed upgrade. Here is what it is worth, and how to sell it.
What changed
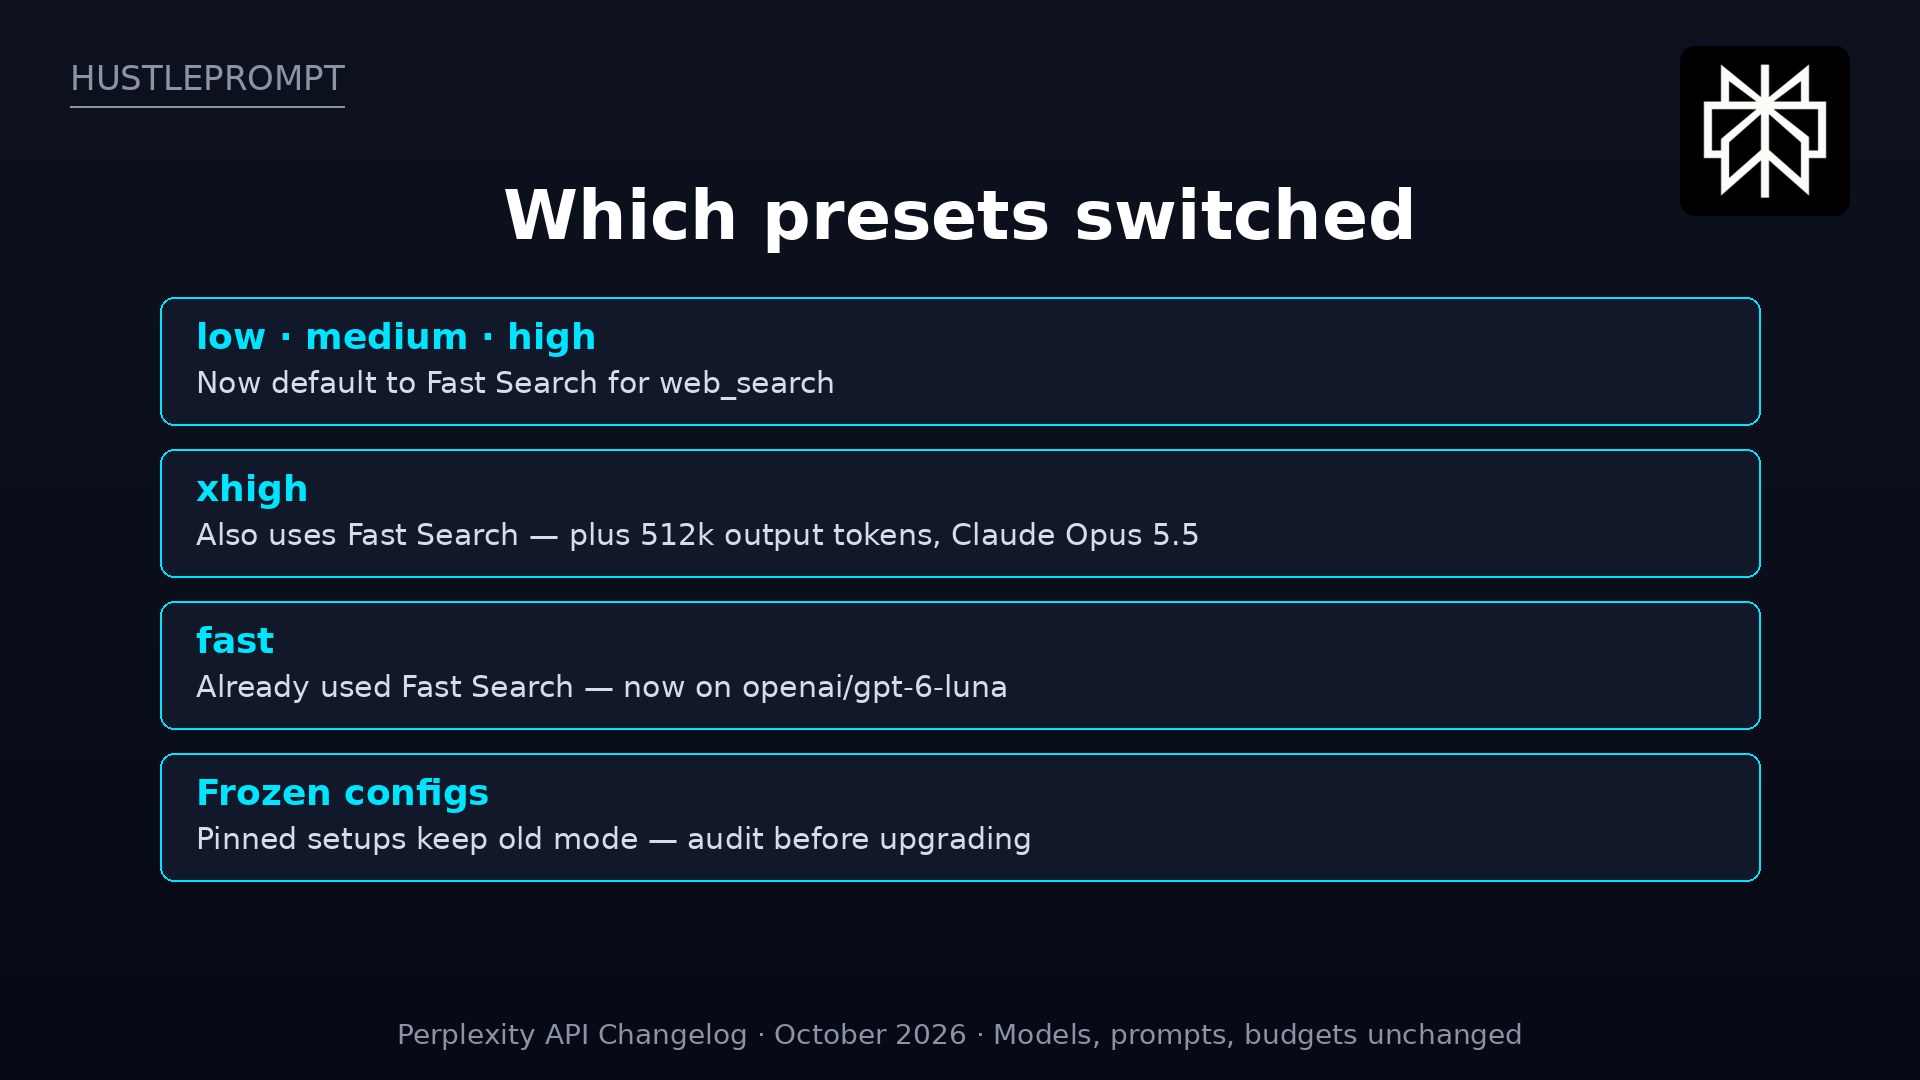
The Agent API’s presets (low, medium, high, xhigh, fast) bundle the model, reasoning effort, tools and budgets for an agent run. The October 2026 changelog moved their web_search calls to Fast Search, Perplexity’s lower-latency retrieval path.
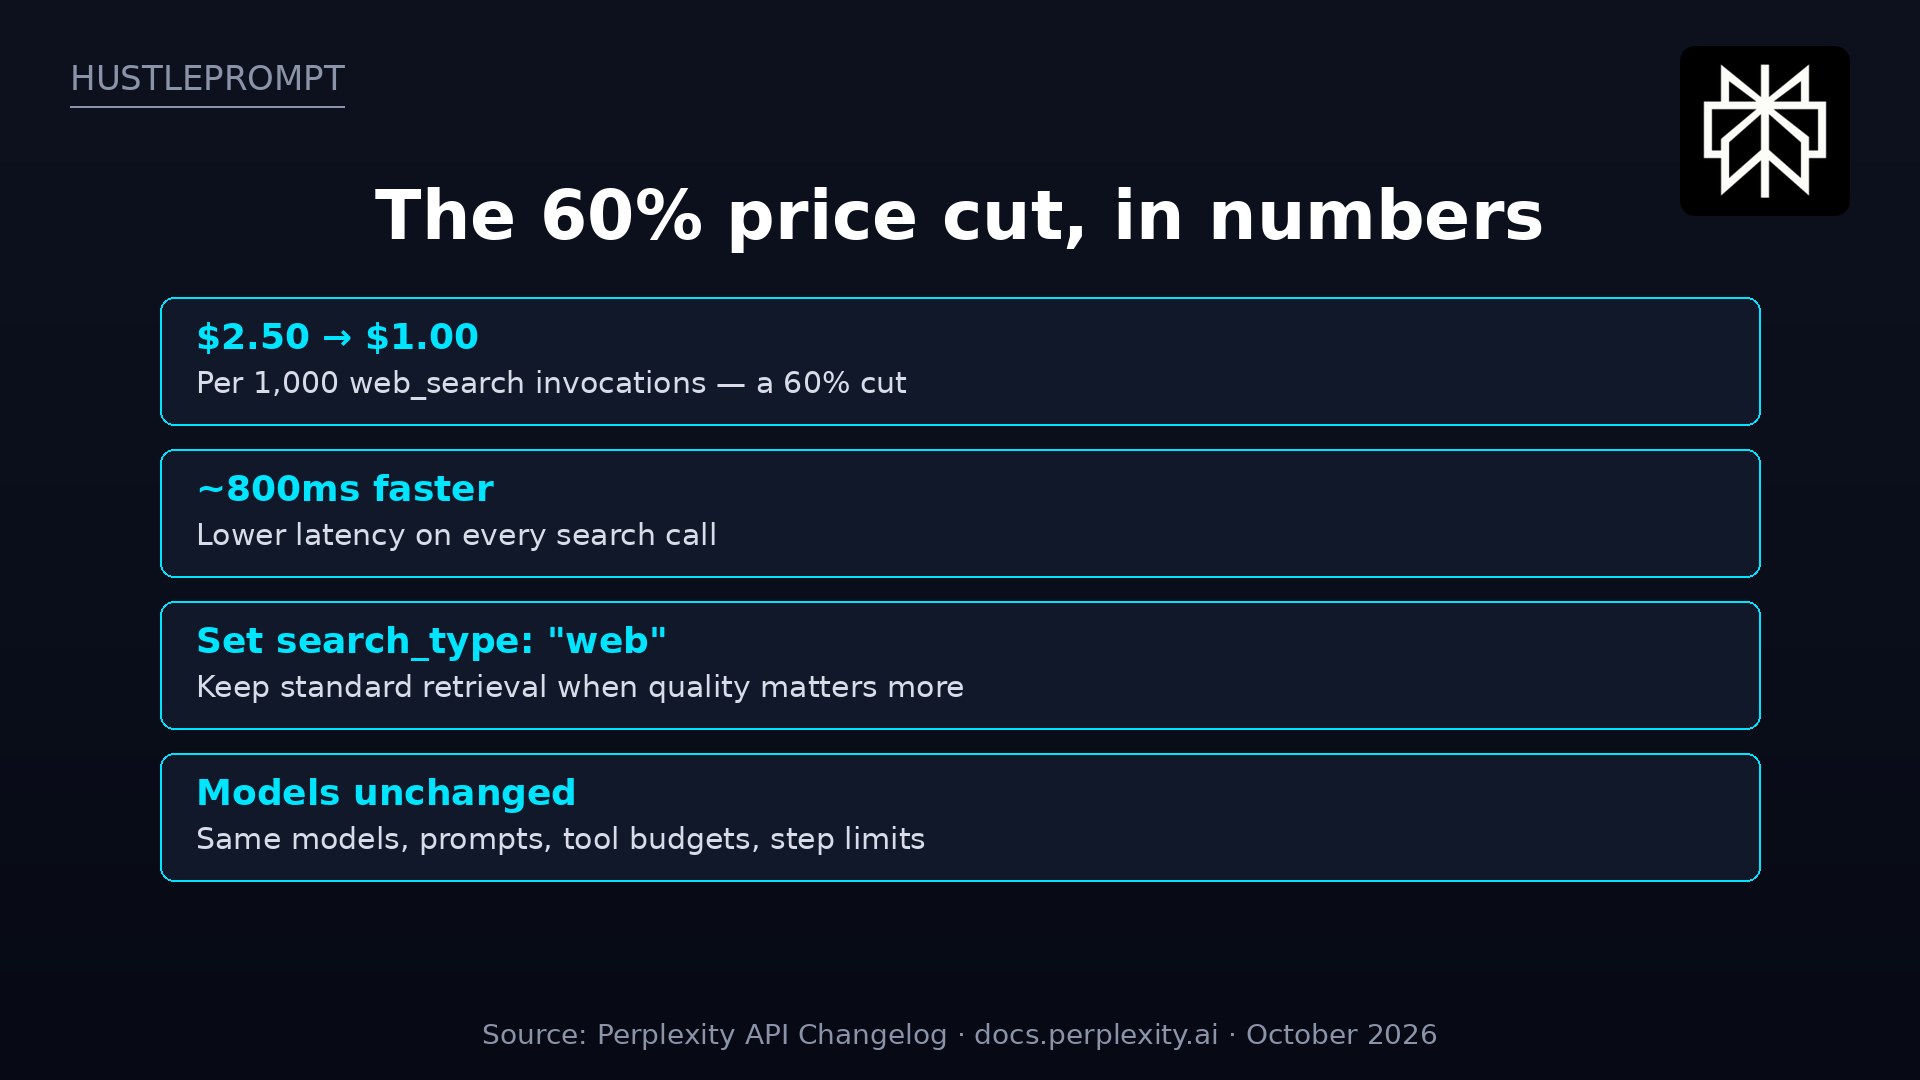
Result: the same agent code now bills 60% less per search call — and answers faster. Set search_type: “web” to keep the old standard path.
All figures from the Perplexity API Changelog (October 2026).
Which presets changed
The changelog even corrects itself: xhigh has used Fast Search since the October update that moved the others:
More October changes worth knowing
The same changelog shipped other cost-relevant updates:
- Preset prompt caching: presets now use stable prompt cache keys automatically — worth ~5% cost reduction for apps that use presets frequently.
- Fast preset refresh: now runs openai/gpt-6-luna with reasoning effort set to none and priority processing (2× standard token prices).
- xhigh output budget: raised to 512,000 tokens, up from 128,000 — 4× headroom for long agent runs.
- Model retirements: older OpenAI IDs (gpt-5.4, 5.4-mini, 5.4-nano, 5.2, 5.1, 5, 5-mini) retire October 24, 2026 — update fallback chains now.
What it is worth in real dollars
The savings compound fast. An agent running 1,000 searches a day drops from $2.50/day to $1.00/day — $45/month. At 10,000 a day, that is $450/month. These figures cover the web-search tool invocation — model tokens bill separately.
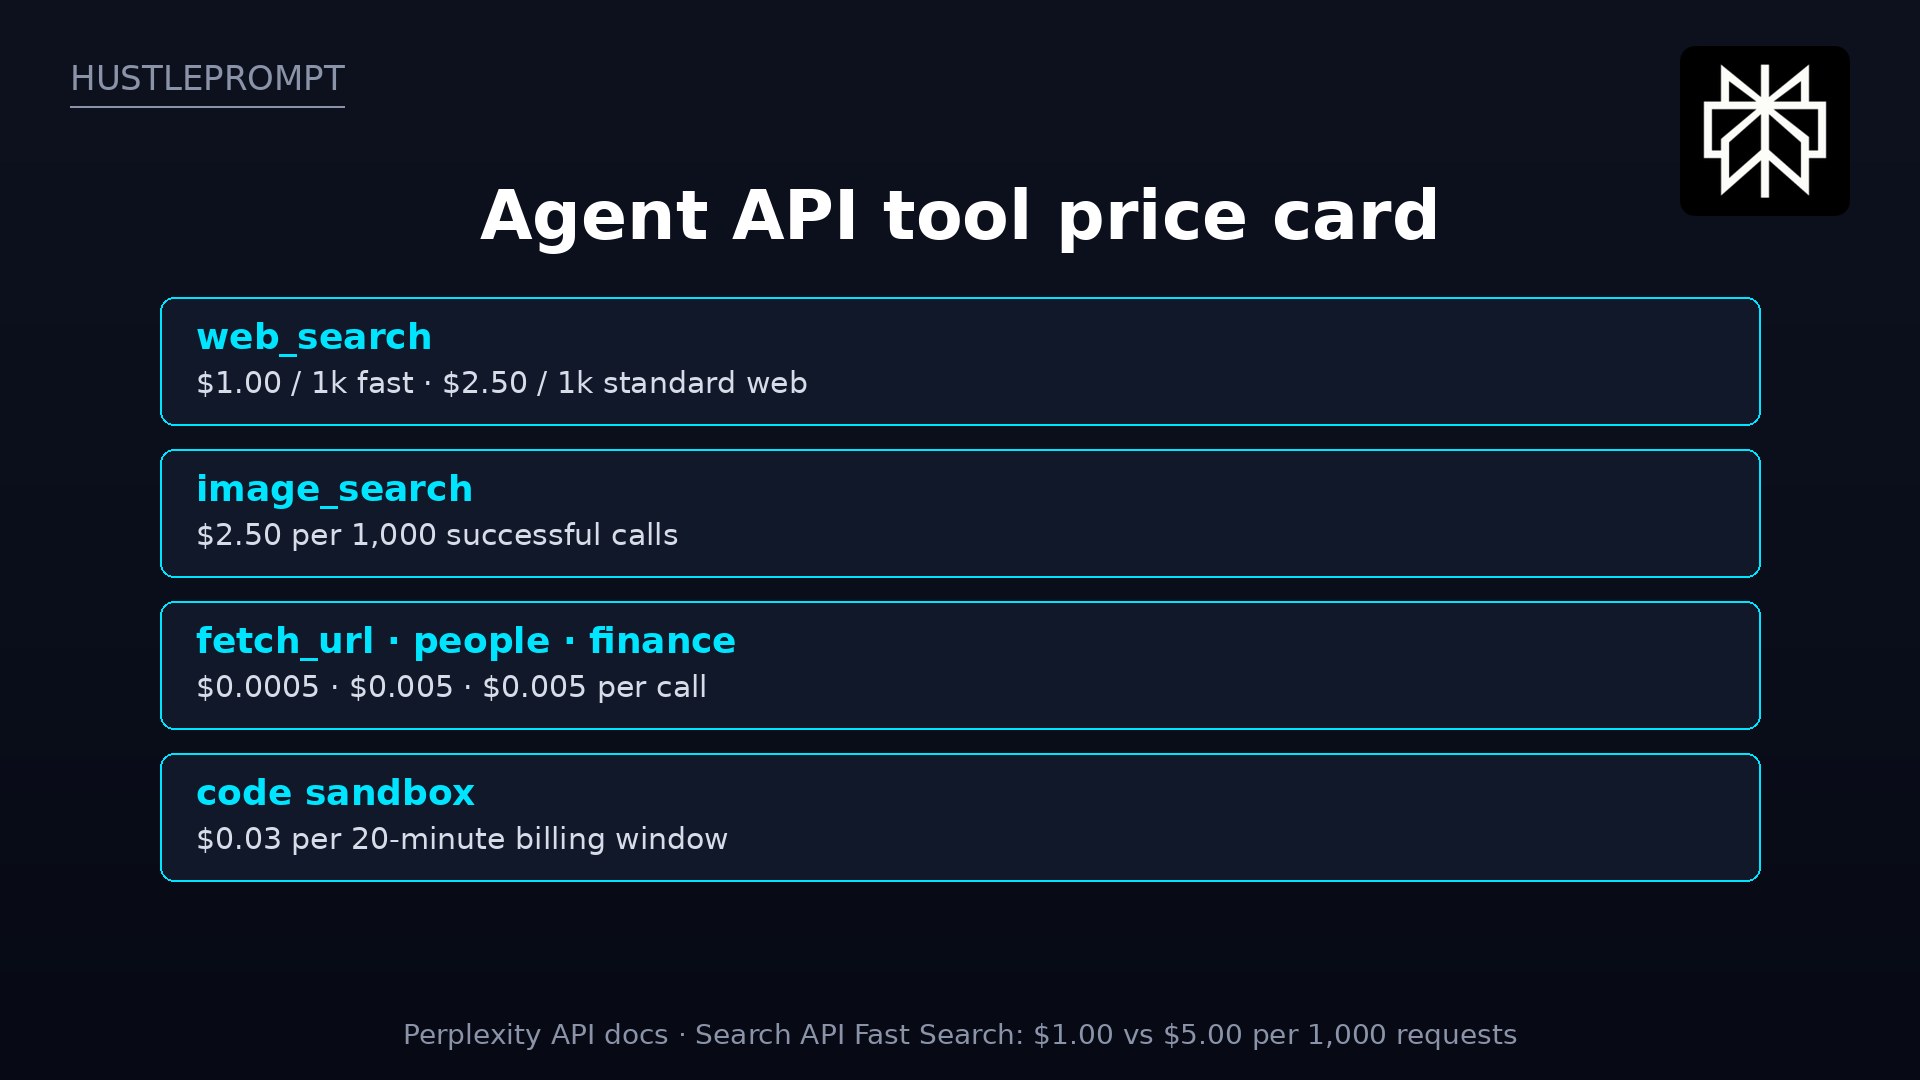
The full tool price card
The raw Search API got its own Fast Search tier too: $1.00 vs $5.00 per 1,000 requests — an 80% cut on raw retrieval.
How to profit: sell the cost-optimization audit
Price cuts create a classic consulting window: everyone’s bill changed, nobody checked:
- Audit frozen vs dynamic presets. Frozen (pinned) configs keep the old $2.50 mode while dynamic presets pay $1.00. Finding and upgrading these is the core of your audit.
- Benchmark fast vs standard per workload. Quality can differ by task — run a representative query set through both, compare source relevance, and set search_type explicitly per workload.
- Right-size the preset. Many teams run high or xhigh out of habit. With the GPT-6 refresh (low/medium on gpt-6-luna, high on gpt-6-sol) and xhigh’s 512k output budget, re-test whether medium now does the job — a downgrade multiplies the savings.
- Package it as a fixed-price audit ($750–$2,000). Deliverable: before/after cost model, explicit search_type recommendations per workflow, frozen-config upgrade plan, and a monitoring checklist. One audit that saves a client $450/month pays for itself in weeks.
- Retainer: quarterly re-audit. Perplexity ships changelog updates constantly — new presets, new models, new tools. A $200/quarter review keeps clients on the cheapest working configuration.
The pitch: “Your AI search bill just dropped 60%. Are you actually getting the discount?”
FAQ
What did Perplexity change in October 2026?
Agent API low, medium, high and xhigh presets now default to Fast Search for web_search: $2.50 → $1.00 per 1,000 invocations (60% cut), ~800ms faster.
Do I need to change my code to get the discount?
No — if you use dynamic presets, the change applies automatically. But apps with frozen (pinned) configurations keep the old mode, so audit those.
Can I still use standard web search?
Yes — set search_type: “web” explicitly on the web_search tool. Useful when quality matters more than speed.
Is Fast Search lower quality?
Perplexity does not claim identical results — validate source relevance and coverage on your own workloads before switching critical pipelines.
What about the raw Search API?
Separate product, same idea: Fast Search costs $1.00 per 1,000 requests versus $5.00 for standard web — an 80% cut. Set search_type: “fast” on Search API requests.
What else changed in the October changelog?
Preset prompt caching (~5% savings), the fast preset moving to openai/gpt-6-luna, xhigh’s output budget rising to 512,000 tokens with Claude Opus 5.5, and older OpenAI model IDs retiring October 24, 2026.
Sources
- Perplexity API Changelog — October 2026 (Fast Search presets, pricing)
- Perplexity Docs — Agent API web search and search_type options