
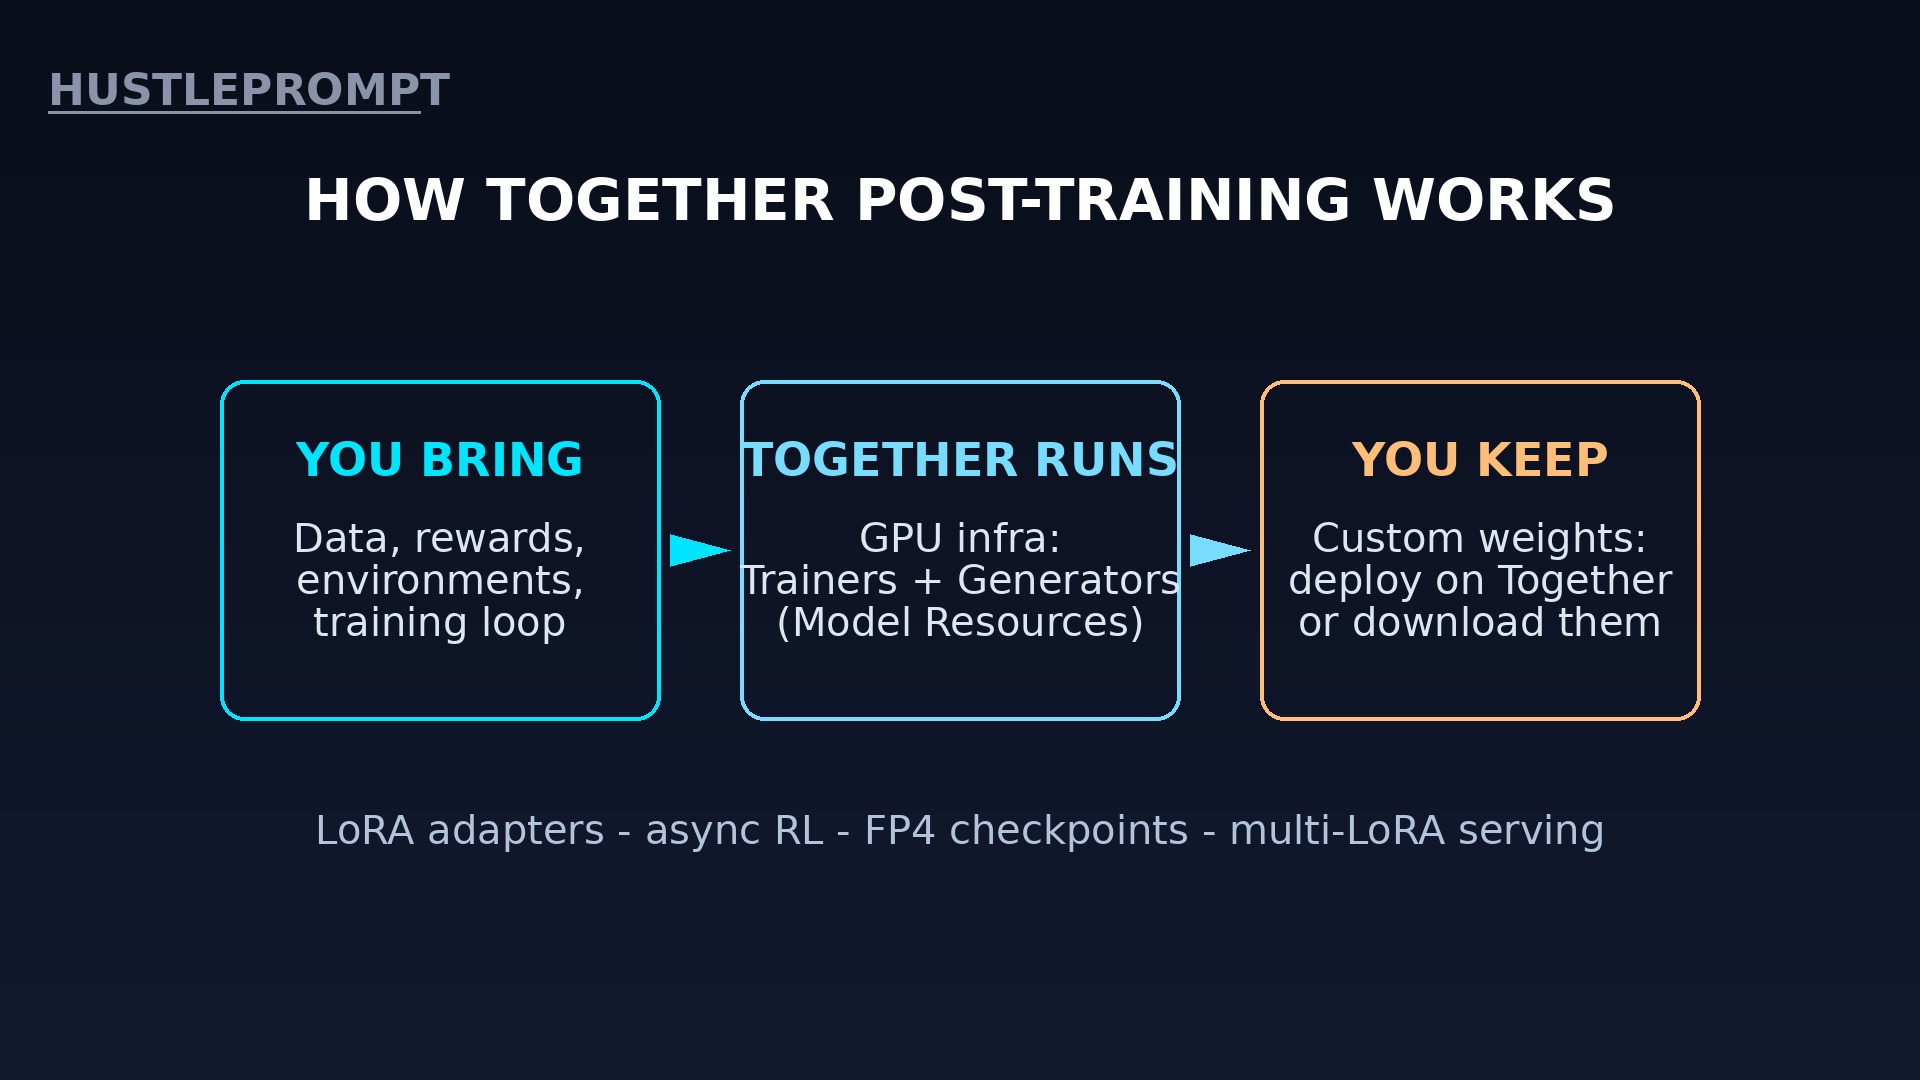
Training a custom AI model used to mean renting a GPU cluster and hiring an ML team. On October 19, 2026, Together AI turned that whole job into a managed service. With the launch of Together Post-Training, you define the RL and SFT loops — your data, your rewards, your environments — and Together runs the GPU infrastructure underneath.
The pitch is simple: post-training is where custom model behavior is actually built — especially for agents that plan, use tools, and recover from mistakes. But running RL at scale means rollout infrastructure, GPU capacity management, and training environments most teams never want to build. Together is productizing that entire layer.
The Announcement: Post-Training as a Managed Service
Together Post-Training is a managed service to build custom models with user-defined RL and SFT loops while Together runs the GPU infrastructure: Model Resources, Training Sessions, Trainer instances, and Generator instances. Here are the facts from the official Together AI blog:
| Detail | Fact |
|---|---|
| Service | Together Post-Training (managed SFT + RL) |
| Announced | October 19, 2026 |
| Intro pricing | $9 per GPU-hour of B200 usage, first eight weeks |
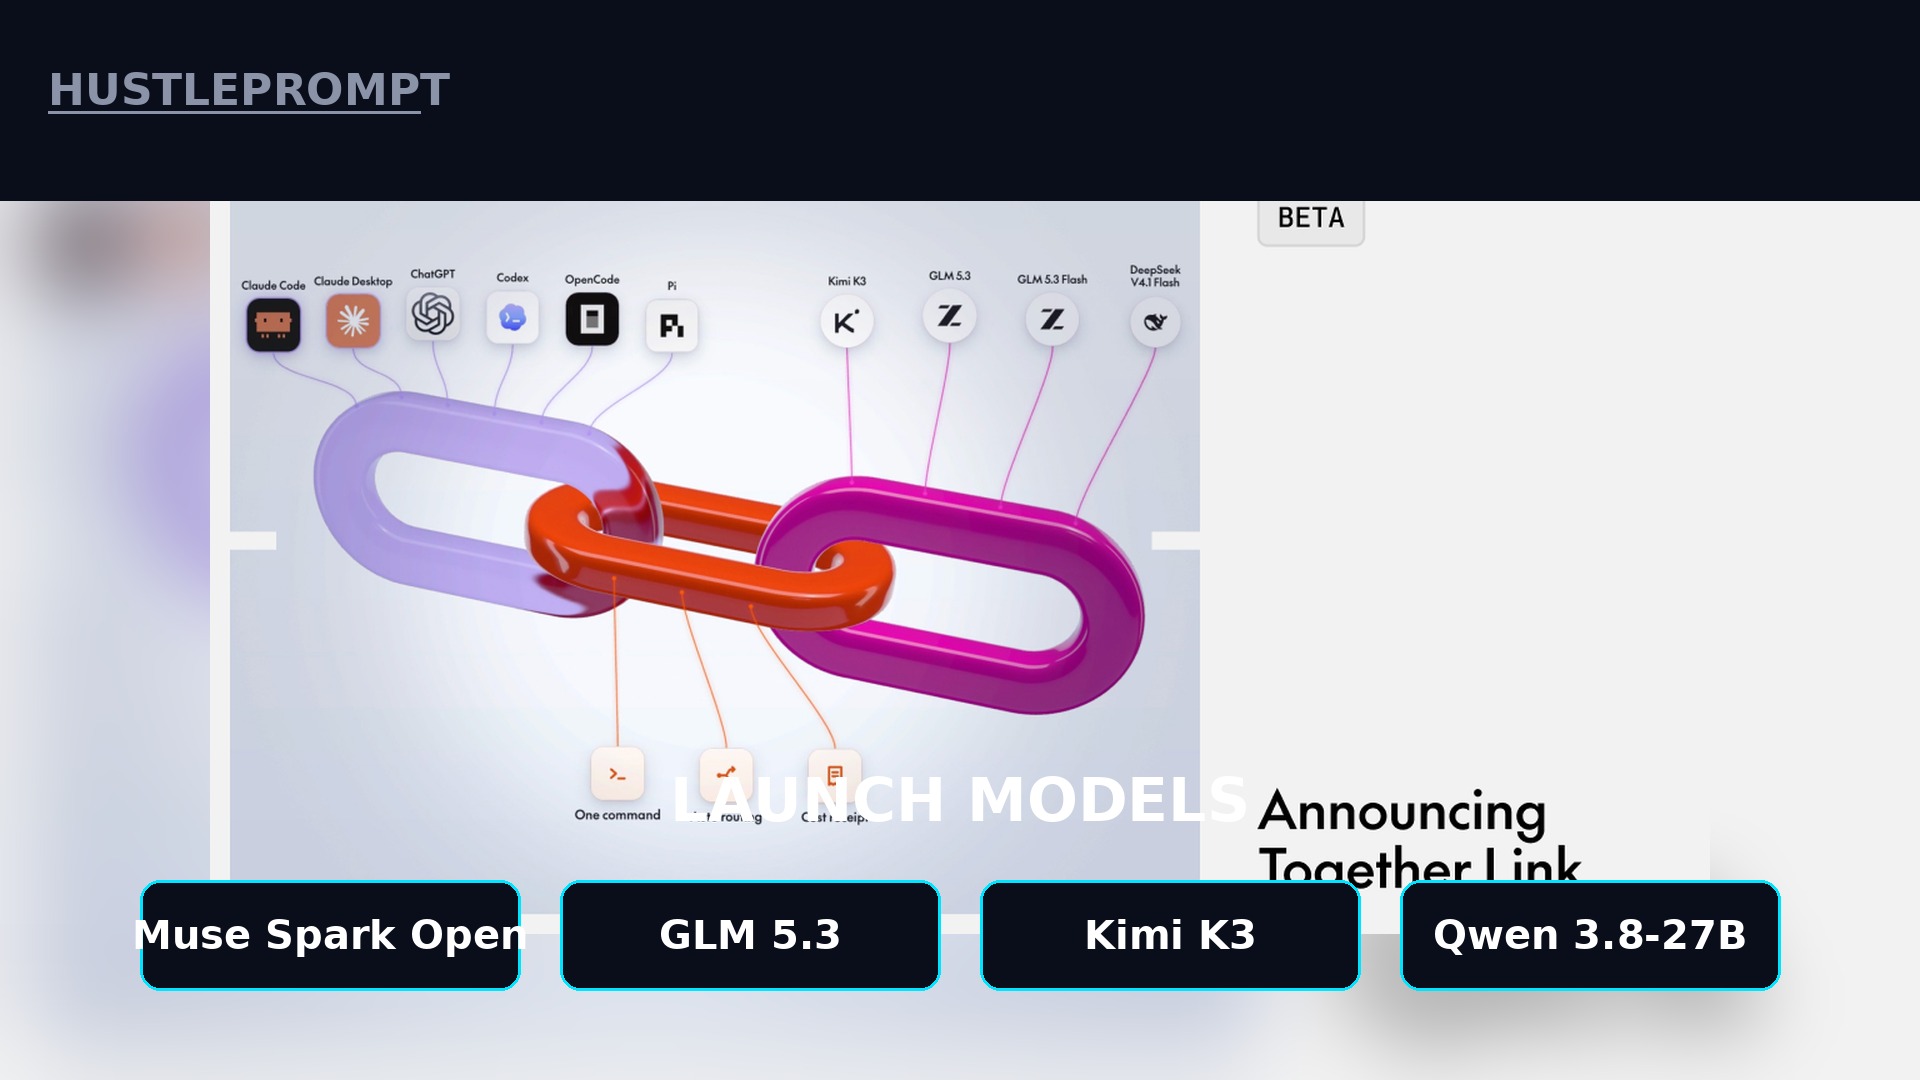
| Launch models | Muse Spark Open, GLM 5.3, Kimi K3, Qwen 3.8-27B |
| Coming soon | Frontier LLMs + efficient small models in coming weeks |
| Beta | Early access ran since April 2026 |
What’s Under the Hood
This isn’t a toy fine-tuning endpoint. The feature list reads like infrastructure for serious agent teams:
- LoRA training, with multiple LoRA adapters sharing the same GPU capacity.
- Full-weight experiments for selected models.
- Asynchronous RL and custom training objectives.
- FP4-precision checkpoint serving for cheaper inference.
- Multi-LoRA adapter serving in Dedicated Model Inference — serve many custom variants off shared capacity.
Early Proof: Who’s Already Using It
Together ran an early-access program since April 2026, and the launch customers are real companies with real workloads:
- Deel — ran up to five concurrent RL experiments on the same GPU capacity.
- Jack & Jill — post-trained a model predicting which candidates a hiring manager will want to meet, matching a closed-source model’s quality in offline evaluations with a cheaper-to-serve open model.
- Collinear AI — researcher Adit Jain: “The Post-Training service has proven to be exceptionally intuitive, flexible, and powerful for scaling sophisticated agentic workloads.”
For companies that want a partner rather than DIY, Together’s forward-deployed engineers work alongside teams across the full post-training lifecycle — model selection, data, environments, evaluations, and shipping an optimized endpoint.
How It Works
You write the training loop. Together runs the hard infrastructure.
How to Profit: Sell Fine-Tuning as a Service
This launch creates a clean agency business. Most companies want a custom model; almost none want to build training infrastructure. Here’s the concrete playbook:
- Pick one vertical — legal, recruiting, support, e-commerce. Vertical AI agents are where custom post-training pays off fastest.
- Package the full loop: data prep + SFT/RL training on Together + evaluation + a deployed endpoint. Clients buy outcomes, not GPU-hours.
- Price per project, pay per hour. At the $9/GPU-hour intro rate, a 24-hour experiment costs $216 and 100 GPU-hours cost $900 — our arithmetic on Together’s figure. Charge $3,000–$8,000 per custom model project and the margin is obvious.
- Partner, don’t hire. Use Together’s forward-deployed engineers as your extended team while you stay lean on the client-facing side.
Frequently Asked Questions
What is Together Post-Training?
A managed service from Together AI that lets developers build custom models with user-defined RL and SFT loops while Together runs the GPU infrastructure.
How much does it cost?
$9 per GPU-hour of B200 usage for the first eight weeks after the October 19, 2026 launch, per the official Together blog.
Which models can I train?
At launch: Muse Spark Open, GLM 5.3, Kimi K3, and Qwen 3.8-27B — all open-weight. Frontier LLMs and efficient small models are coming in the following weeks.
Do I keep the trained weights?
Yes. You can deploy the custom model on Together or download the weights.
Who is it for?
Teams building vertical AI agents that need custom behavior — especially agentic RL workloads — without building their own training infrastructure.
How long does the intro pricing last?
Eight weeks from launch — through mid-December 2026 — after which standard pricing applies.