
Seventy percent. That’s how much MiniMax claims it cut agent API costs with its newest model. MiniMax M3.1 Flash, launched October 19, 2026, is a 428-billion-parameter mixture-of-experts model that the company says delivers “a generational leap in agentic tasks” — with inference nearly three times faster and usage costs down 70%.
At $0.15 per million input tokens, M3.1 Flash costs half of its predecessor M3 — and half of DeepSeek V4.1 Flash, which launched just two days earlier on October 17. For anyone running AI agents at scale, this is the price war everyone was waiting for.
M3.1 Flash pricing: half of everything
MiniMax set flat, brutally simple pricing — no tiers:
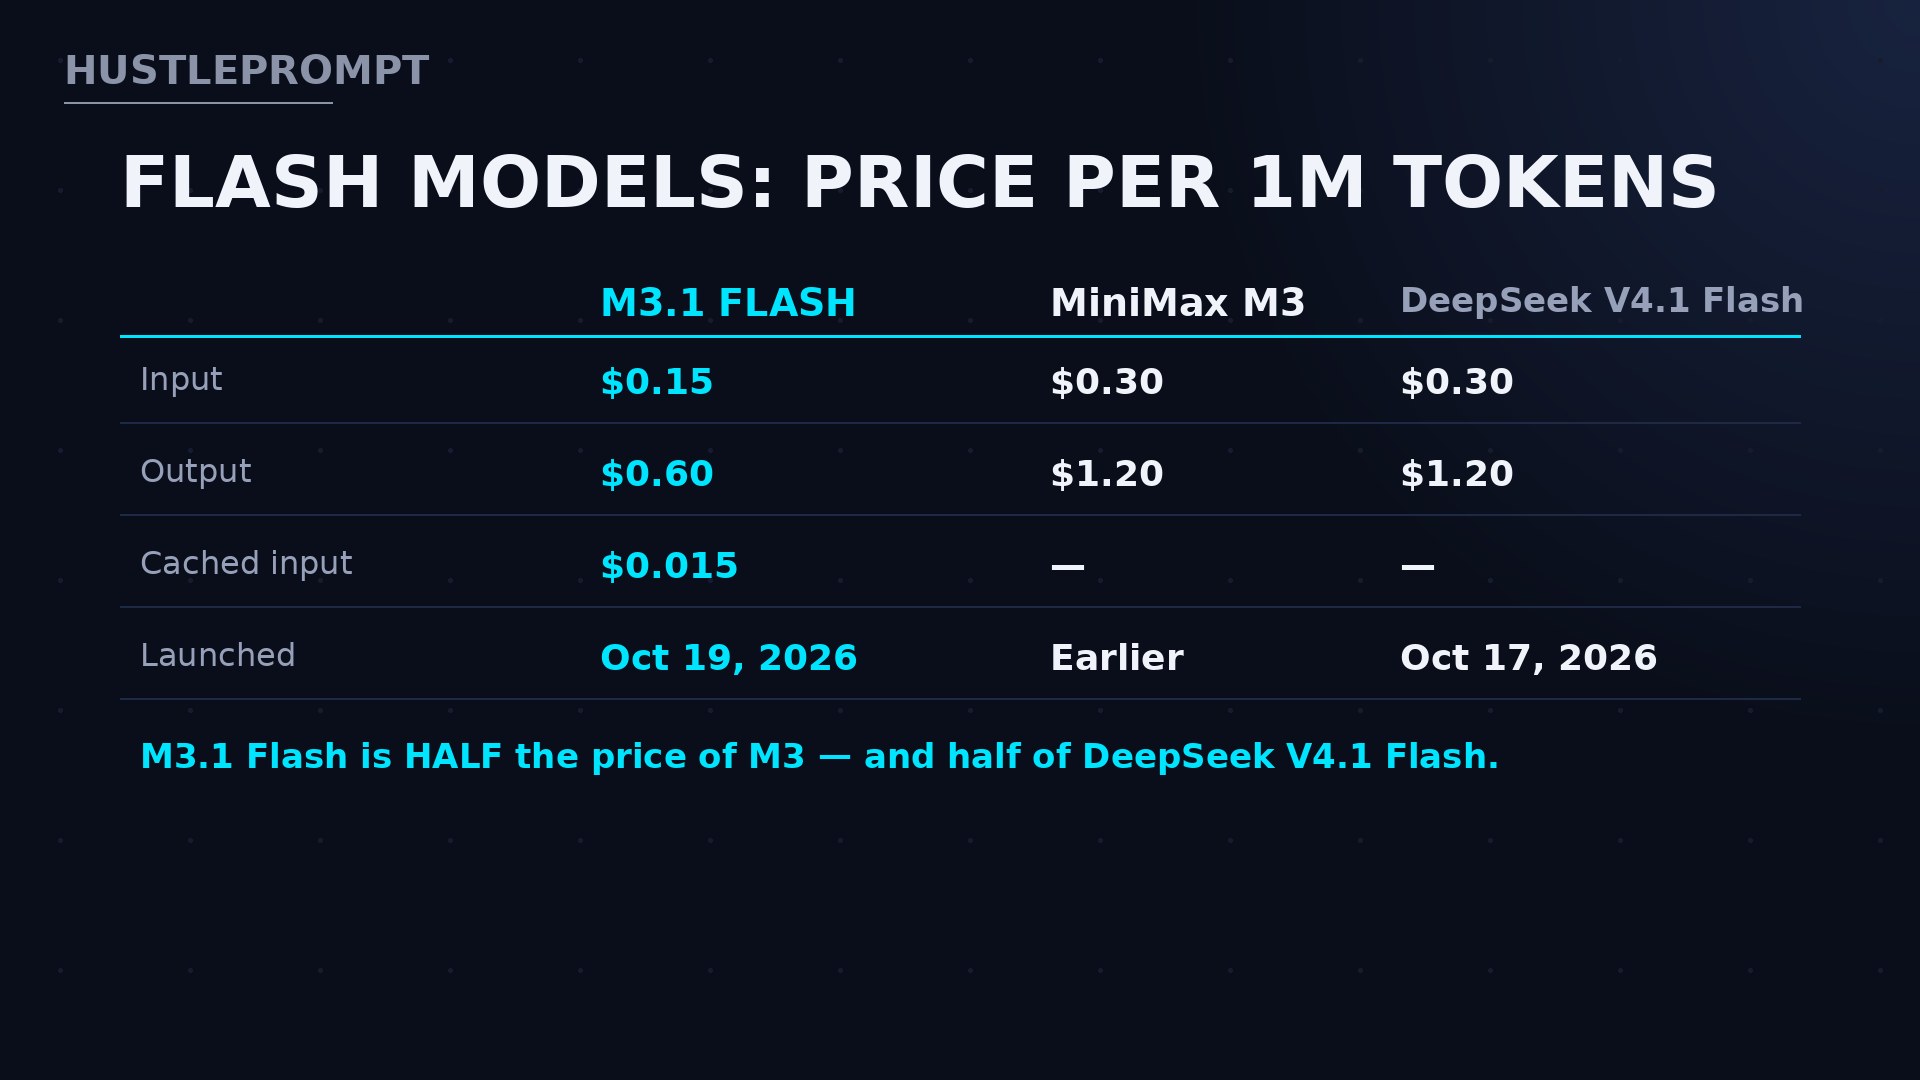
Cached input tokens drop to just $0.015 per million — aimed squarely at agent workloads, where the same context gets reused call after call.
What the model actually is
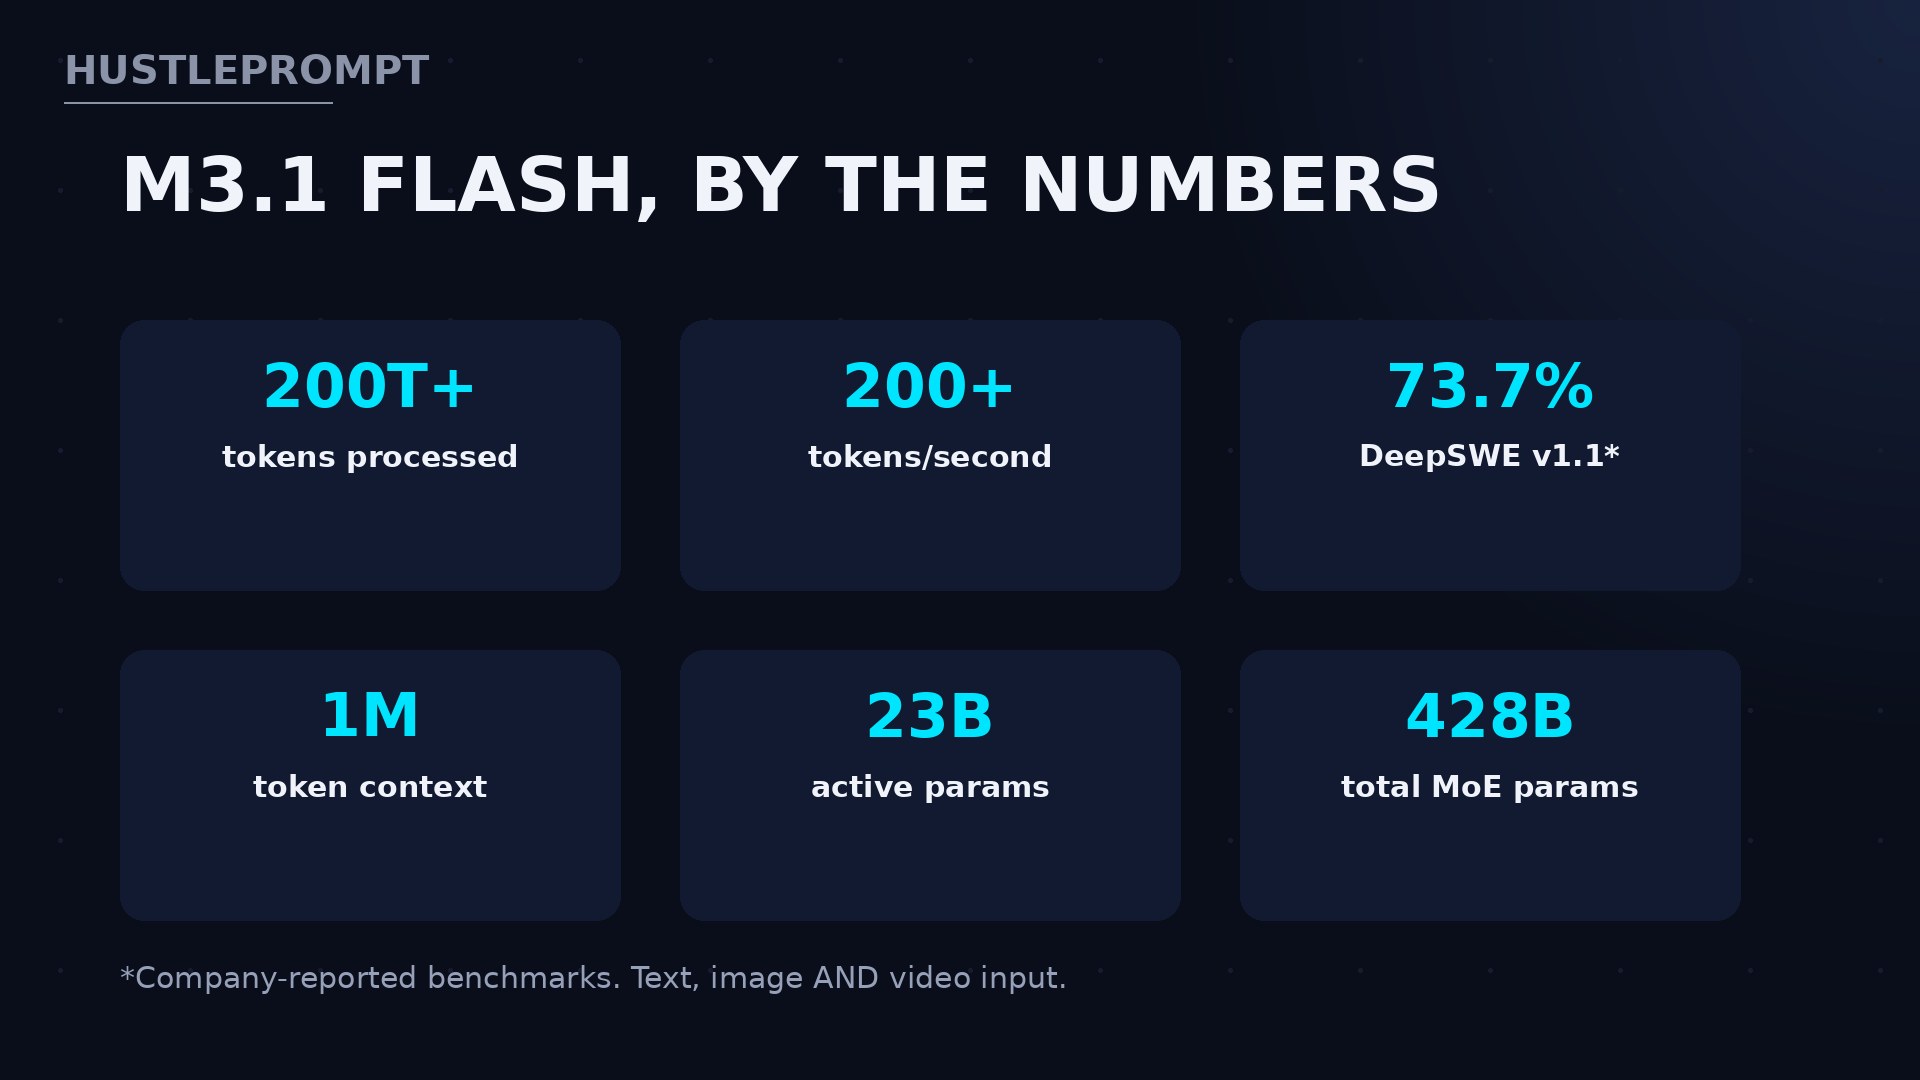
Under the hood, M3.1 Flash is a 428B-parameter MoE (mixture of experts) with only ~23B active parameters per token — a huge knowledge base where only a small slice fires at once.
- 1M-token context window — room for entire codebases or long agent histories
- Text, image AND video input — true multimodal agent work
- 200+ tokens per second in everyday use, median P50 of 170+ TPS — per MiniMax, “nearly 3x faster” than its predecessor via more aggressive sparsity
The “Flash” line is MiniMax’s speed-and-cost-optimized family: built for agentic coding, computer use, and cybersecurity rather than raw chat.
The benchmarks — MiniMax’s own numbers
Every score below comes from MiniMax’s official announcement. No independent lab has replicated them yet — treat them as the company’s claims:
*All figures are MiniMax’s own company-reported numbers, not independent verification. M3.1 Flash also scored 42 on the Artificial Analysis Intelligence Index — 13 points above M3.
“As a next-generation Flash model, M3.1 Flash delivers a generational leap in agentic tasks, coding, Computer Use and cybersecurity, while making online inference nearly three times faster and reducing usage costs by 70%.”
“Space Bunny” was M3.1 Flash all along
The stealthiest part of this launch: before October 19, the model was already live — anonymously. MiniMax released an early version as “Space Bunny” on LMArena and OpenRouter, where it quietly processed 200T+ tokens and became OpenRouter’s #1 model for 10 straight days (56.7T tokens on OpenRouter alone).
Ships anonymously as “Space Bunny” on LMArena and OpenRouter.
Processes 200T+ tokens anonymously. Hits #1 on OpenRouter for 10 straight days (56.7T tokens).
MiniMax unmasks it as M3.1 Flash on October 19, 2026 — with public benchmarks to back the hype.
Why does that matter? Those anonymous leaderboards are the closest thing AI has to a blind taste test — millions of real users chose Space Bunny without knowing it was MiniMax.
How to profit: concrete moves today
The money angle is simple: agent cost per task is collapsing. A cost analysis reported by oossa.com puts M3.1 Flash’s estimated cost at roughly $0.22 per task based on the published rates. Capture it:
- Try it free while the promos last. Free on OpenRouter for 72 hours from Oct 19 and on the Vercel AI Gateway until Oct 22.
- Re-price your agent services. If you sell automation or coding help, 70% lower inference costs go straight to margin — or let you undercut competitors on pricier models.
- Swap endpoints, not code. Anthropic- and OpenAI-compatible endpoints make switching an existing agent a one-line URL change.
- Mark October 23. Model weights release then (license undisclosed) — relevant if you want to self-host or fine-tune. A bigger “Pro” model is coming later.
The catches (there are two)
No launch this aggressive comes without tradeoffs — flagged by third parties before MiniMax could spin them:
- Hallucination concerns: tech-insider.org raised questions about hallucinations on agentic tasks — keep a human in the loop on unsupervised production work.
- Factual accuracy is middling: in The New Stack’s test, M3.1 Flash scored 56% correct vs DeepSeek V4.1 Flash’s 43% — better than its price rival, but still a coin flip on hard facts. Verify outputs.
Where to use it right now
- MiniMax API (platform.minimax.io) — Anthropic- and OpenAI-compatible endpoints
- M Plan subscription — MiniMax’s own paid tier
- MiniMax Code — the company’s desktop coding app
- OpenRouter & Vercel AI Gateway — free promos around launch (check current status)
FAQ
What is MiniMax M3.1 Flash?
A 428B-parameter mixture-of-experts model launched October 19, 2026, optimized for agent tasks, coding, computer use, and cybersecurity — priced at $0.15 per 1M input tokens.
How much does M3.1 Flash cost per million tokens?
$0.15 for input, $0.60 for output, and $0.015 for cached input. That’s half the price of MiniMax M3 ($0.30/$1.20) and half of DeepSeek V4.1 Flash ($0.30/$1.20).
How fast is M3.1 Flash?
MiniMax reports 200+ tokens per second in everyday use with a median P50 of 170+ tokens/sec — “nearly 3x faster” than its predecessor thanks to more aggressive sparsity.
What was “Space Bunny”?
The stealth name for an early version of M3.1 Flash, released anonymously on LMArena and OpenRouter. It processed 200T+ tokens and ranked #1 on OpenRouter for 10 straight days before MiniMax revealed it.
Can I try M3.1 Flash for free?
Yes — it launched free on OpenRouter for 72 hours (from Oct 19) and free on the Vercel AI Gateway until Oct 22. Check whether the promos are still live.
Will M3.1 Flash be open weights?
MiniMax plans to release the model weights on October 23, 2026, but the license terms have not been disclosed yet.