
Three rival AI labs now charge exactly the same price for the same invisible thing: $0.10 per million cached tokens. Anthropic cut its Claude Sonnet 5.5 cache-read rate to that number on October 7, 2026. OpenAI lists it for GPT-6.1 Sol. Google’s Gemini 4 Argon discounts cached input to it too.
That is not a coincidence. It is a market admitting, in public, what an AI agent actually spends its budget on. An agent does not just answer once. It re-reads its instructions, its tool definitions, and its conversation history on every single turn. The re-read is the bill.
Here is why this matters beyond a pricing footnote: one of those $0.10 rates has an expiry date. Google’s Argon price doubles on December 1, and its cached rate doubles with it. Anyone building an agent business on today’s rate card without reading the December card is pricing a product with a seven-week-old map.
What Is Actually Trending
Prompt caching is the feature behind the number. When you send a request to a language model, the model first processes your whole prompt — the system instructions, the tool definitions, the documents — before it writes a single word of reply. That first phase is called prefill, and it costs tokens.
Caching stores the processed beginning of the prompt, the prefix. If the next request starts with exactly the same prefix, the provider skips reprocessing it and bills the cached tokens at a much lower rate. The catch is strict: caching is prefix-only. Change one character near the top — a timestamp, a shuffled tool list — and the cache breaks.
For a chatbot answering one question, caching barely matters. For an agent working a 40-turn session, it is everything. Every turn resends the same system prompt and tool schemas, plus the growing conversation. By turn 40, most of what the model reads is text it has already read 39 times. Without caching, you pay full price for that re-read every time.
That workload shape explains the convergence. Chat-era billing priced what the model produced. Agent-era billing prices what the agent re-reads to decide. Three labs, competing fiercely on model quality, all landed on the same cached number within weeks because the agent workload forced their hands: the cached rate became the real rate, and no lab could afford to be the expensive one to re-read.
The Evidence: Three Rate Cards, One Number
Start with Anthropic, because its change is the cleanest to verify. On October 7, 2026, Anthropic lowered Claude Sonnet 5.5 cache reads from $0.20 to $0.10 per million tokens — a 50% cut to that one line of the bill. Everything else stayed put.
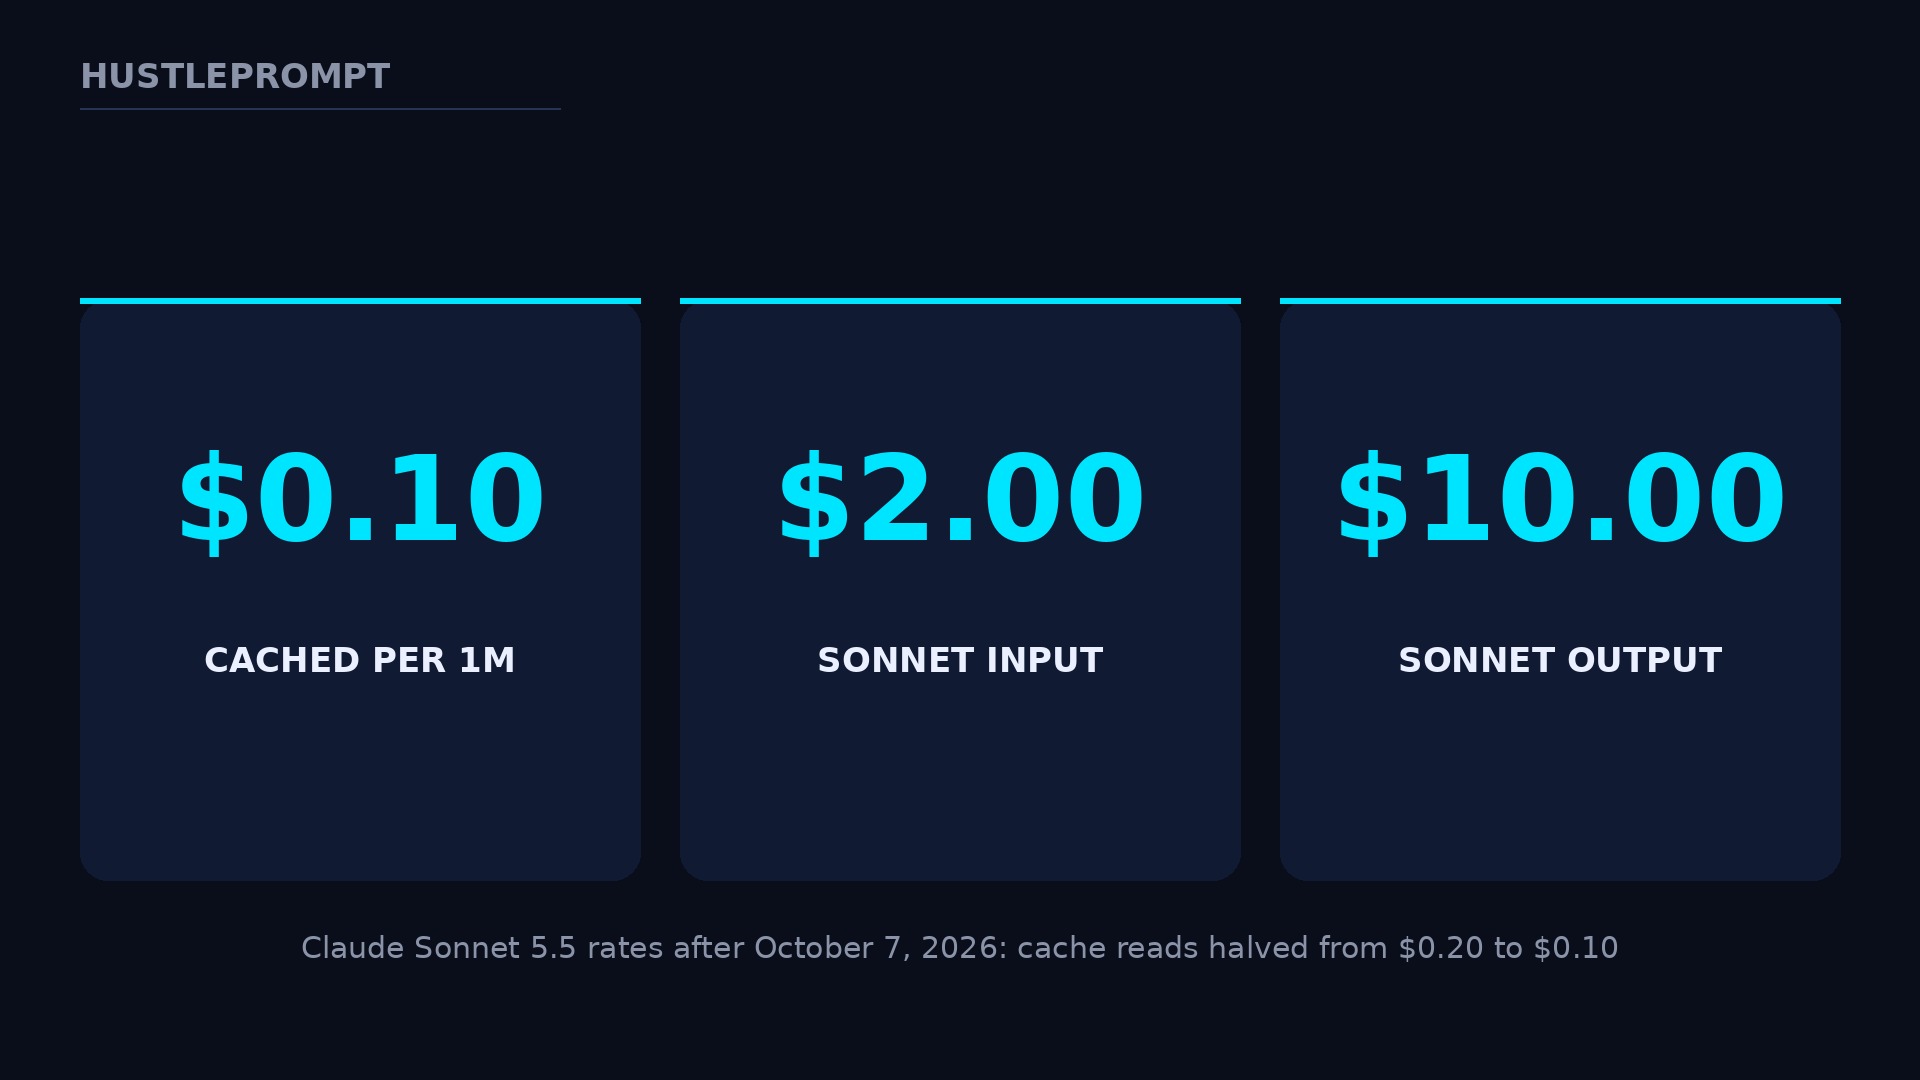
Sources: Unite.AI, “Anthropic Slashes Claude Sonnet 5.5 Cache-Read Cost by 50%” (Oct 7, 2026) · WorldNgayon, “Prompt Caching Prices 2026: the Best Guide to the $0.10 Convergence” · ClaudeBeat, Sonnet 5.5 cache-read analysis (Oct 11, 2026).
Anthropic says the cut makes most agentic work about 20% cheaper, because cache reads are a large share of agent tokens. Halving one line item does not halve the bill: output, uncached input, and cache writes still bill at full rates.
The worked example makes the scale concrete. Take a 10,000-token system prompt that an agent re-reads 100 times in a session. At the old $0.20 cache-read rate, those reads cost $0.20. At the new $0.10 rate, they cost $0.10. That is real money at volume. The same arithmetic shows what an uncached design costs: one million uncached input tokens at $2.00 versus $0.10 cached. The gap between a cacheable agent and a careless one is 20 to 1 on the re-read.
OpenAI’s GPT-6.1 Sol is reported at the same $0.10 cached figure, and Argon reaches it via a 95% discount on its $2.00 input rate.
The December Cliff Nobody Priced In
Now the part that turns a pricing observation into a business deadline. Google opened Gemini 4 Argon to paying developers on October 13, 2026, at $2 per million input tokens and $10 per million output tokens. Those are introductory rates. They end November 30, 2026.
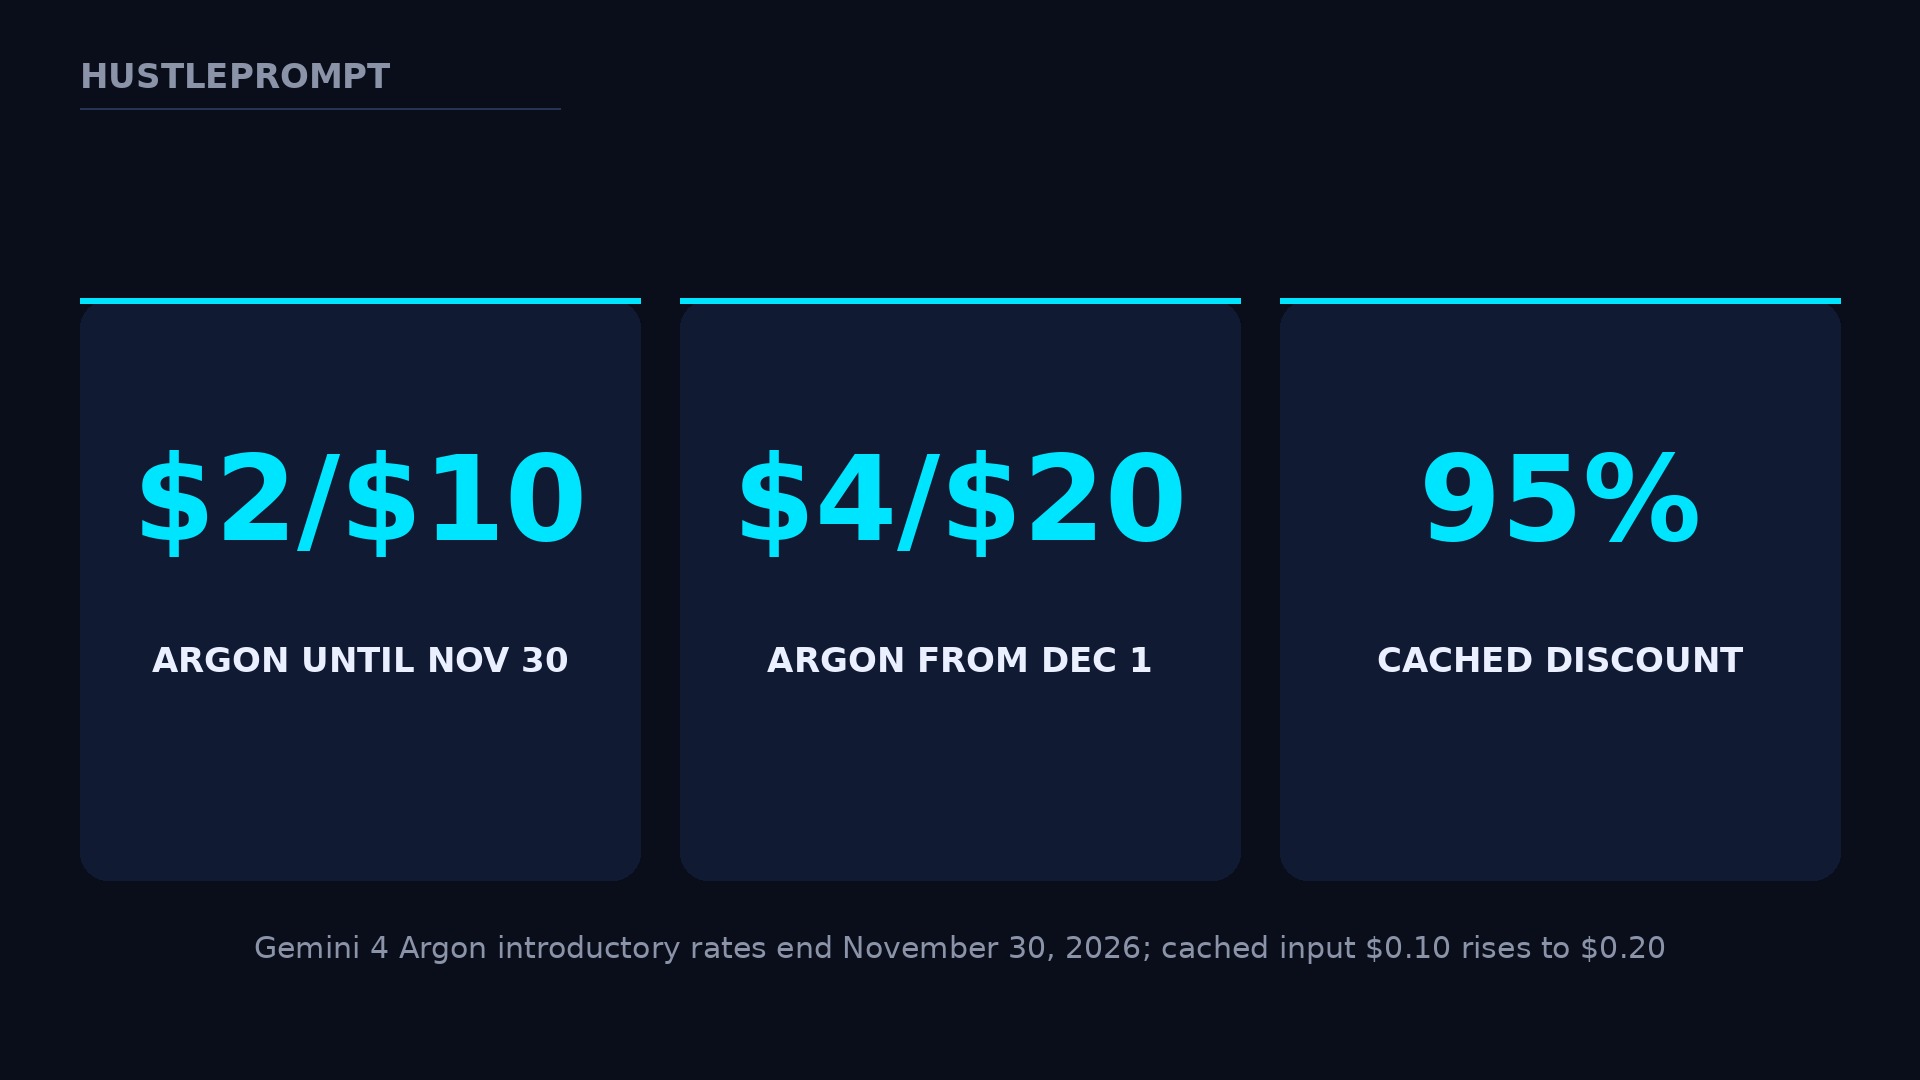
Sources: The AI News Report, “Gemini 4 Argon Is Open to Developers at $2/$10. On December 1, the Price Doubles” (Oct 14, 2026) · MLQ, “Google Opens Gemini 4 Argon at Introductory API Price” (Oct 14, 2026).
Every Argon rate doubles at once, including batch and flex, which stay at half the standard rate on both sides of the cliff. Cached input doubles too, from $0.10 to $0.20, so the $0.10 convergence breaks on December 1 for Argon unless Google extends it. There is no free tier, and Argon is not on the Google AI Pro plan’s API access.
Put a real job next to the cliff. Artificial Analysis spent $2,407 running its full test suite on Argon at launch prices, against $5,324 for GPT-6 Astra and $8,708 for Claude Opus 5.5. At the December 1 price, the same run would cost about $4,814 on the source’s arithmetic — still below both rivals, but nearly double. Any margin that only works at $2/$10 will break in the December invoice.
The wider context is a market growing fast and failing often. One industry summary puts the AI agents market at $29.2 billion in 2026 rising to $65.5 billion in 2027, while Gartner warns that over 40% of agentic projects will be cancelled by the end of 2027 over cost, unclear value, and weak controls. Those are projections, not guarantees — but together they describe the exact trap: demand is real, and the projects that die will disproportionately be the ones whose unit economics were never engineered.
Build for the Cache, in Three Moves
The prompt order is the cost structure. Stable first, changing last, or you pay full price.
Stable prefix first
System prompt, tool definitions, and fixed documents go first and never change order. This is the text the cache can reuse.
New message last
The user’s new message and fresh results go at the end. Anything after the first difference bills at full price.
Check the cache hit
Confirm cached tokens appear in the usage data. If the hit rate is zero, the design is broken — silently, with no error.
How to Profit From This Trend
Do not sell “cheaper AI.” Sell a bill that stays cheap. Every team running an agent has the same blind spot: nobody owns the token bill, and the failure is silent. Nothing errors when caching breaks. The response looks identical while the invoice quietly doubles. That silence is the product.
The entry offer is a cache audit: one week, one agent, one report showing cached versus uncached tokens, the hit rate, and the December repricing of the client’s actual workload. The rebuild that follows is prompt-order surgery — freezing the prefix, removing timestamps from the top of the prompt, making tool lists deterministic — not a model swap. Then comes the retainer: monthly monitoring, because every new feature a client ships can break the prefix again.
Prices below are my estimates based on comparable freelance API and automation rates, not market data:
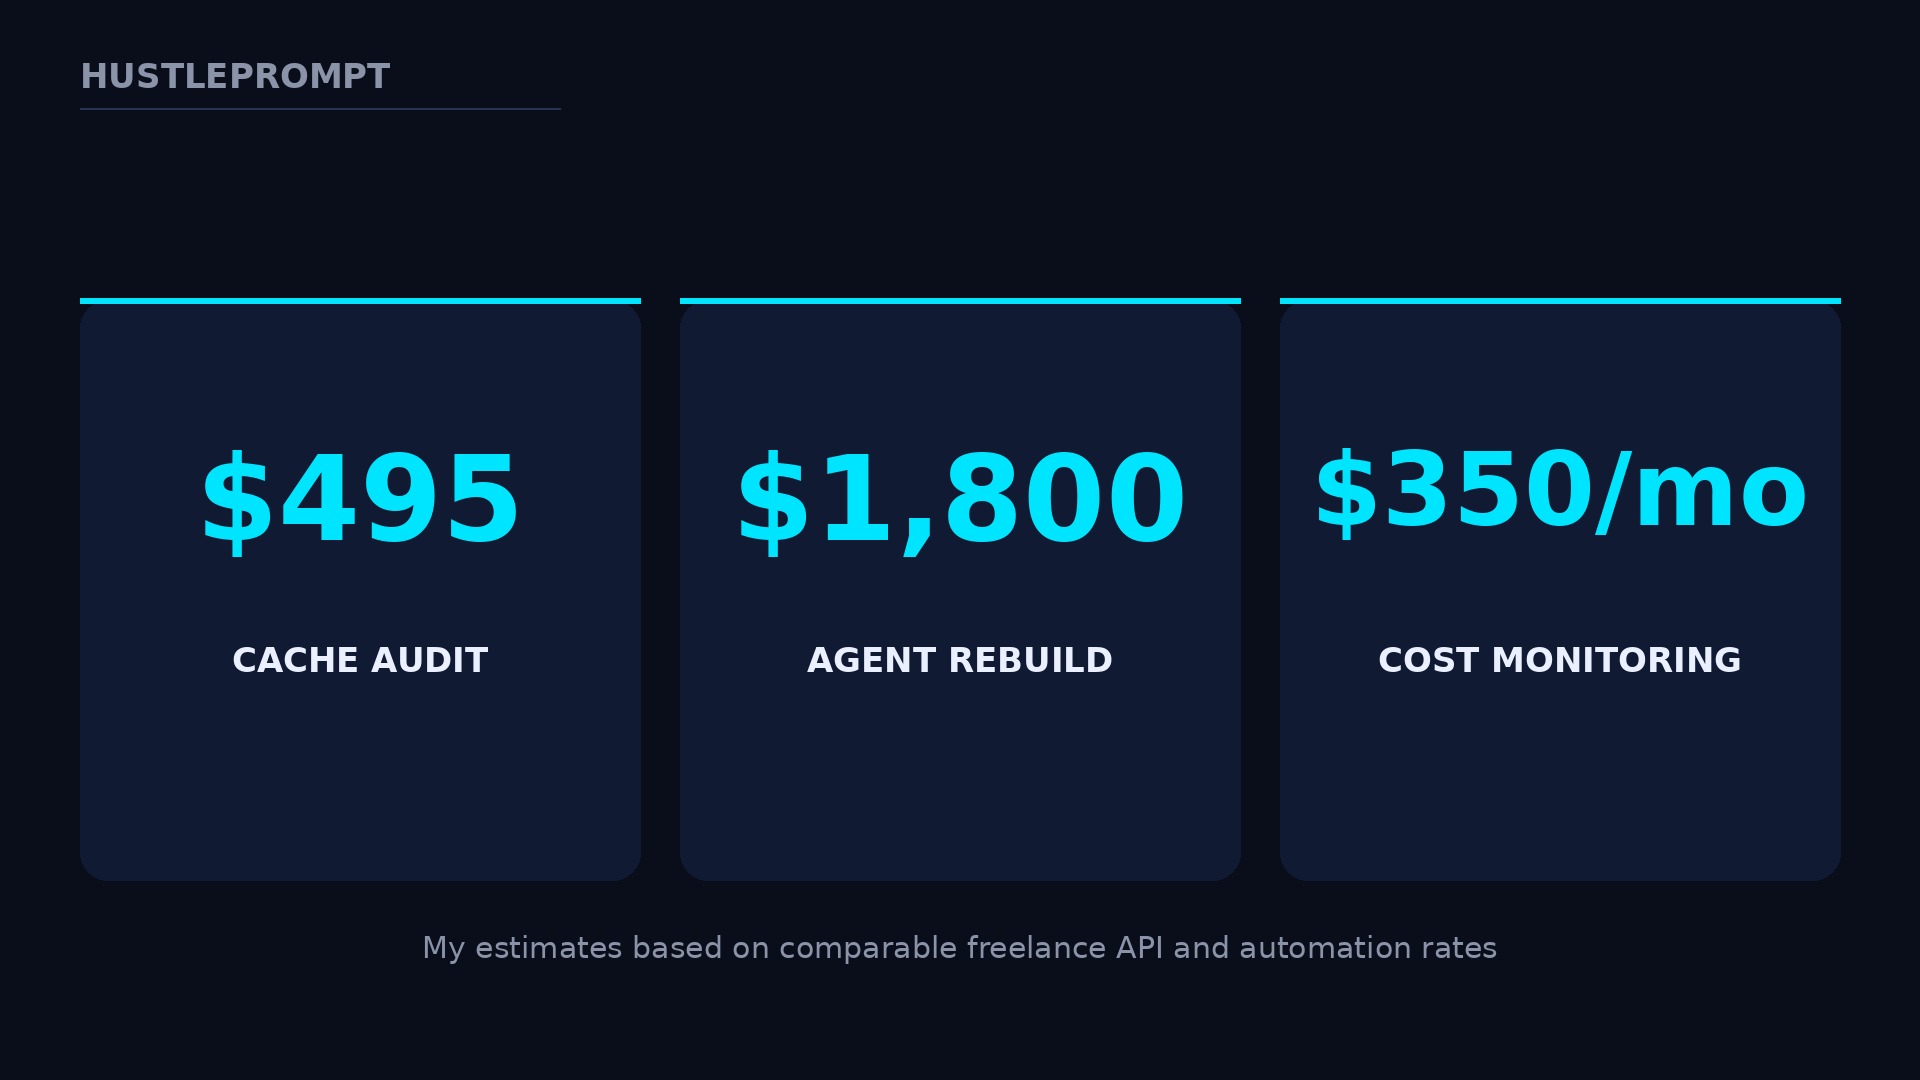
Lead with the December date, not the $0.10 number: “Your Argon agent costs X today and 2X on December 1 at the same usage. Here is the workload repriced, and the rebuild that keeps the cached share high.” That sells the audit, the rebuild, and the retainer at once.
What to Do This Week
- Price every Argon quote at $4/$20. Treat November as a rebate, not the rate. If the margin fails at December prices, the quote is wrong today.
- Freeze one agent’s prefix. Move system instructions, tool schemas, and fixed documents to the top, in a fixed order, and put timestamps and changing data last.
- Measure the hit rate. Run the agent twice with an identical prefix and confirm cached tokens in the usage data. Zero cached tokens means a silent design bug.
- Batch what can wait. Asynchronous work at half price — batch or flex — stacks with caching on Argon and survives the December doubling in proportion.
Watch: how prefix caching reuses a prompt’s processed state — and why one changed word can break it. Watch on YouTube.
Where This Is Heading
The cached rate stops being news. Once every lab charges $0.10, caching becomes table stakes: expected, invisible, noticed only when missing. Competition moves to cache-write premiums, batch discounts, and subscription credits.
December repricing becomes a sales event. Every Argon workload gets repriced on December 1, and every vendor email about it is a free lead list for cache auditors. The sellers who already hold their clients’ November usage data will write the December quotes. Everyone else will be reacting to invoices.
Cost engineering becomes a job title. The projects that survive Gartner’s cancellation warning will be the ones with someone watching the token bill like payroll. That someone can be you, on retainer.
Frequently Asked Questions
What is prompt caching, in plain English?
The provider saves the processed beginning of your prompt. When the next request starts the same way, it reuses that work instead of reprocessing it, and bills the reused tokens at a much lower cached rate.
Why did three labs all land on $0.10?
Because agents re-read the same context every turn, the cached rate became the real rate for agent workloads. Each lab’s agent strategy required matching the cheapest cached price, so the number converged within weeks.
Does Anthropic’s cut halve my Claude bill?
No. It halves one line item — Sonnet 5.5 cache reads, from $0.20 to $0.10. Output, uncached input, and cache writes are unchanged, and Anthropic puts the typical agentic saving at about 20%.
What exactly changes for Gemini 4 Argon on December 1?
Standard rates double from $2/$10 to $4/$20 per million input/output tokens, cached input rises from $0.10 to $0.20, and batch/flex rates double from $1/$5 to $2/$10. The introductory period ends November 30, 2026.
Why does my cache hit rate read zero?
Usually the prefix is not stable: a timestamp, a reordered tool list, or changing data near the top breaks the exact prefix match. Caching fails silently, so check cached tokens in the usage data rather than trusting the design.
Should I build on Argon before December 1?
Yes, but price the build at December rates. November pricing is a rebate, not the rate — and a workload that only works at $2/$10 will break in its first full December invoice.